你的浏览器版本过低,可能导致网站不能正常访问!
为了你能正常使用网站功能,请使用这些浏览器。

【安富莱——DSP教程】第8章 BasicMathFunctions的使用(一)

[复制链接]
baiyongbin2009 发布时间:2015-3-18 11:33
特别说明:完整45期数字信号处理教程,原创高性能示波器代码全开源地址:链接
' T. G8 I9 z) U1 _! u
第8章 BasicMathFunctions的使用(一)

- G, H- s- z: x
    本期教程开始学习ARM官方的DSP库,这里我们先从基本数学函数开始。本期教程主要讲绝对值,加法,点乘和乘法四种运算。
    8.1 绝对值(Vector Absolute Value)
    8.2 求和(Vector Addition)
    8.3 点乘(Vector Dot Product)
    8.4 乘法(Vector Multiplication)
' F  {: S! {( c' ]! c* V
8.1 绝对值(Vector Absolute Value)
    这部分函数主要用于求绝对值,公式描述如下:
    pDst[n] = abs(pSrc[n]),   0 <= n < blockSize.
    特别注意,这部分函数支持目标指针和源指针指向相同的缓冲区。
8.1.1 arm_abs_f32
    这个函数用于求32位浮点数的绝对值,源代码分析如下:
  1. /**        
    8 O+ _2 ^  D  K
  2. * @brief Floating-point vector absolute value.                                                    (1)8 Y* q) _4 Z$ n# e3 e' A: s: U, W
  3. * @param[in]       *pSrc points to the input buffer        
    4 U* c) t5 s: ~/ f5 g; Y7 n
  4. * @param[out]      *pDst points to the output buffer        / O. A' D) c, \( W: L" ?: z
  5. * @param[in]       blockSize number of samples in each vector        
    & `; l! h4 R! z  L
  6. * @return none.          M. L9 e9 p8 l9 D9 m# n
  7. */3 g5 w& q% g: D* X3 L

  8. ! l0 h7 s* G3 u3 w8 _
  9. void arm_abs_f32(                                                                                  (2)" j3 @) s1 z" v) w3 c, U3 r
  10.   float32_t * pSrc,
    : g. N& T' h' r3 s, A) L; p% T
  11.   float32_t * pDst,
    8 q$ f4 z. G. \2 ?2 Z& B
  12.   uint32_t blockSize)& K2 o; L4 ]6 H4 ?. E
  13. {
    $ a, l4 ?6 V  g/ j
  14.   uint32_t blkCnt;                               /* loop counter */
    + P0 U/ l+ |, l( E8 ~7 n4 K

  15. 7 V: v& b3 s6 X: l9 h. G0 C
  16. #ifndef ARM_MATH_CM0_FAMILY                                                                        (3)* O) K, }, J5 x$ m; e2 Z
  17. / D8 F) ~/ {( }; F$ X) e
  18.   /* Run the below code for Cortex-M4 and Cortex-M3 */
    7 m1 I' N4 j) t. W# h3 L
  19.   float32_t in1, in2, in3, in4;                  /* temporary variables */
    $ ]8 r9 x# t% O7 o, e& ]
  20. 1 p0 U" ]: N1 r6 {8 b: z
  21.   /*loop Unrolling */& t* A; `& U. x2 {- a
  22.   blkCnt = blockSize >> 2u;                                                                        (4)
    3 D/ l, h3 i" _5 t+ c

  23. : u; E; i2 G7 o$ _0 D* G6 X  g4 g
  24.   /* First part of the processing with loop unrolling.  Compute 4 outputs at a time.   
    ! k  G4 \: m  d
  25.    ** a second loop below computes the remaining 1 to 3 samples. */* V, l' @  ]# P+ J! i. |( ?
  26.   while(blkCnt > 0u)
    " h" t0 M+ \8 E/ e" h% K5 I
  27.   {
    " \, J* P  L  {; ~* E
  28.     /* C = |A| */. ?0 O6 Y7 C9 g' o
  29.     /* Calculate absolute and then store the results in the destination buffer. */
    8 ?9 n( o+ d) J3 h- s
  30.     /* read sample from source */% _/ B% _7 k9 \4 @1 T6 ~
  31.     in1 = *pSrc;
    ! Z; m' X- b& P. u
  32.     in2 = *(pSrc + 1);
    0 U) W5 T) h6 @$ Y2 X; L0 p* }" ]
  33.     in3 = *(pSrc + 2);
    ( E0 u) i; O* [9 S: U
  34. 1 U2 s4 X# g6 U2 f( u- r: o# P2 |
  35.     /* find absolute value */# u& c. g1 s' S, S* K* T
  36.     in1 = fabsf(in1);                                                                             (5)
    4 ^/ {9 }' `5 M7 m2 n

  37. 2 l9 \4 U2 F5 q
  38.     /* read sample from source */# J! F. j6 a( R& o2 b% p
  39.     in4 = *(pSrc + 3);2 s  D) t' C9 s- n5 ?% m& Q2 d. U
  40. + u" h( f( e0 y3 m( Y9 Y' ^4 @
  41.     /* find absolute value */+ |4 k( w+ G' I* e" l
  42.     in2 = fabsf(in2);  M, \/ I# d, T  g/ @5 Q7 `

  43. 7 f4 T6 X" Y+ o+ g1 {- t6 Q3 _
  44.     /* read sample from source */
    6 [5 W2 `$ a) J
  45.     *pDst = in1;: i& j) F! T" E+ [. h, q
  46. 4 n% d' ]: i$ ]! f
  47.     /* find absolute value */
    2 d7 T0 G# j' X
  48.     in3 = fabsf(in3);2 b) t! q- k' ^

  49. ( Y4 l( w: u6 k) T# e% D
  50.     /* find absolute value */5 |, V% J! t; W- }5 b( J" G( ?
  51.     in4 = fabsf(in4);
    : ?( U* h/ l0 i, x- L; E' B3 d2 V
  52. - e8 h2 E6 }+ n- X
  53.     /* store result to destination */9 M) L  P- g& Q7 j8 r$ l
  54.     *(pDst + 1) = in2;# S, _3 B. \: n0 F
  55. 3 F% e" v1 u1 |
  56.     /* store result to destination */
    , d& c4 S1 B) T6 w) X: c
  57.     *(pDst + 2) = in3;
    & \/ X  b. K  F$ y- }3 v2 r2 m+ K" ?" W
  58. 7 B$ a) m- c" G4 U# [
  59.     /* store result to destination */
    ' v- G# f9 D# a' o
  60.     *(pDst + 3) = in4;, C" g+ [' [# G

  61. % p5 L0 g7 m  z7 P- K

  62. & @: E) S2 C( y% [" m
  63.     /* Update source pointer to process next sampels */                                            (6)
    ! v3 c, A% e; u2 I4 b2 e
  64.     pSrc += 4u;* k" o* \; R; V  M3 g4 G  s) \9 V
  65. " B. ~0 J* N3 x1 n1 i( C
  66.     /* Update destination pointer to process next sampels */' {  _  {) `6 }6 U1 Q: |' h9 c6 E
  67.     pDst += 4u;
    / ]  |( ?3 v$ F; Y* R, l

  68. 2 q1 w- ?& Y# i$ x
  69.     /* Decrement the loop counter */
    2 g1 R8 U' w4 E9 V! M. Z& V) E
  70.     blkCnt--;
    . P: v' [. p2 N1 E
  71.   }
    9 ~: @' u/ D, l- [- L
  72. 8 m1 T! [4 w8 K, ^
  73.   /* If the blockSize is not a multiple of 4, compute any remaining output samples here.   
    ( H" ^3 }4 R# K* u- W
  74.    ** No loop unrolling is used. */* v- q$ j) r  ^% U
  75.   blkCnt = blockSize % 0x4u;
    ! |6 q. w- V' a5 n* j5 z

  76. 4 I9 U+ M. g  A6 P
  77. #else                                                                                             (7)
    7 m0 A, |* O- g$ @
  78. ( C/ y1 |! q, B& W
  79.   /* Run the below code for Cortex-M0 */; m+ I$ G3 N, i' k  X- G: k* r

  80.   ~4 A& P, B( k! t- ?7 R$ w
  81.   /* Initialize blkCnt with number of samples */$ J4 T$ Y  l( z
  82.   blkCnt = blockSize;
    9 w( e0 Q: O" N0 D% G, @: ]

  83. ( _6 D1 k3 q$ r  n# `
  84. #endif /*   #ifndef ARM_MATH_CM0_FAMILY   */( S) I0 w( ~1 c

  85. - b" N) E, A; Y$ U( i! Y
  86.   while(blkCnt > 0u)                                                                              (8)" b6 \9 U' l6 z3 K8 i1 J
  87.   {* B, o; m5 f4 P1 @, H1 `
  88.     /* C = |A| */
    4 E7 n% p! r0 b1 k( b! N) h- ?
  89.     /* Calculate absolute and then store the results in the destination buffer. */. |, }2 ?" _5 q& w9 u) i
  90.     *pDst++ = fabsf(*pSrc++);
    1 o9 @  c+ R3 Q5 }: j

  91. * P) j$ u: y% l/ S! a1 Z
  92.     /* Decrement the loop counter */
    6 `: }4 Q! T& f& [0 Q8 e
  93.     blkCnt--;. t1 }  e- C2 d2 G
  94.   }
    5 S, F. r/ ?4 D* N
  95. }
复制代码
1. 在这里简单的跟大家介绍一下DSP库中函数的通用格式,后面就不再赘述了。
    (1) 基本所有的函数都是可重入的。
    (2) 大部分函数都支持一组数的计算,比如这个函数arm_abs_f32就可以计算一组数的绝对值。所以如果只是就几个数的绝对值,用这个库函数就没有什么优势了。
    (3) 库函数基本是CM0,CM3和CM4都支持的(最新的DSP库已经添加CM7的支持)。
    (4) 每组数据基本上都是以4个数为一个单位进行计算,不够四个再单独计算。
    (5) 大部分函数都是配有f32,Q31,Q15和Q7四种格式。
2. 函数参数,支持输入一个数组进行计算绝对值。
3. 这部分代码是用于CM3和CM4内核。
4. 左移两位从而实现每4个数据为一组进行计算。
5. fabsf:这个函数不是用Cortex-M4F支持的DSP指令实现的,而是用C语言实现的,这个函数是被MDK封装起来的。
6. 切换到下一组数据。
7. 这部分代码用于CM0.
8. 用于不够4个数据的计算或者CM0内核。
8.1.2 arm_abs_q31
    这个函数用于求32位定点数的绝对值,源代码分析如下:
  1. /**    " ~1 R- n; t* ]
  2. * @brief Q31 vector absolute value.   
    0 i: N6 C/ @( a3 ^
  3. * @param[in]       *pSrc points to the input buffer   
    4 m5 r. [, s% K; i8 D
  4. * @param[out]      *pDst points to the output buffer    ; ~0 B9 g8 k* d; ]
  5. * @param[in]       blockSize number of samples in each vector    3 ]0 O( v- Y, A5 I' T# W! u" t
  6. * @return none.   
    ( [# I0 ~" |% Y+ I" P
  7. *   
    " C8 y  ~9 {6 t  }5 V& b7 I
  8. * <b>Scaling and Overflow Behavior:</b>                                                              (1)
    # `1 }" A- H$ C& @2 X8 J* ]: C" \
  9. * \par   
    ; T! r2 C) _0 B1 p
  10. * The function uses saturating arithmetic.    & R; Q6 d6 Y' v2 t* h9 m
  11. * The Q31 value -1 (0x80000000) will be saturated to the maximum allowable positive value 0x7FFFFFFF.   
    ; t* s9 r0 i( Q/ [' `
  12. */
    ' N9 {5 ?% b5 X7 g

  13. $ t0 Q( g$ W6 v
  14. void arm_abs_q31(! a- {. o, s& P: [* l
  15.   q31_t * pSrc,7 G! X# a* P2 ^" `
  16.   q31_t * pDst,
    " G! m; w# B1 ?  B* N& d
  17.   uint32_t blockSize)! R) Q0 u% k0 y& n0 ?
  18. {9 x* F/ e! m2 E3 s3 u0 l
  19.   uint32_t blkCnt;                               /* loop counter */
    0 U  E, d+ c5 l" e. g! J+ y
  20.   q31_t in;                                      /* Input value */
    ) ?+ x: M0 z6 b) w

  21. & C5 f( {3 N! U) K' |" w
  22. #ifndef ARM_MATH_CM0_FAMILY
    ) O8 o% S' j. B- D3 [9 Y9 Y
  23. " ~. l6 N  d' u; [3 s' w6 n% I  f& {
  24.   /* Run the below code for Cortex-M4 and Cortex-M3 */
    # A: T* Q' F3 P
  25.   q31_t in1, in2, in3, in4;0 T* h* d& C( I$ @6 y

  26. ' ?" c5 x) \+ n9 g$ z, m9 s2 n& ~
  27.   /*loop Unrolling */
    0 d1 N2 s4 U7 X6 t0 Z. \
  28.   blkCnt = blockSize >> 2u;
    # y; C" W7 O/ y$ u% [! A! B' N
  29. ; \- }( m6 N! F0 L6 f
  30.   /* First part of the processing with loop unrolling.  Compute 4 outputs at a time.   
    3 Q9 c* G/ z8 M" k
  31.    ** a second loop below computes the remaining 1 to 3 samples. */7 J9 N! n$ E+ A0 W, n. N
  32.   while(blkCnt > 0u)' K" `# p& J: _
  33.   {
    " \7 r  l/ V6 p' B: u0 o/ h
  34.     /* C = |A| */
    - w8 U$ ?0 A; b/ c
  35.     /* Calculate absolute of input (if -1 then saturated to 0x7fffffff) and then store the results in the destination buffer. */
    / w- u9 r+ |. b4 s3 ?9 e1 h" c
  36.     in1 = *pSrc++;6 i/ A0 [5 _  b( i$ @+ T
  37.     in2 = *pSrc++;
    + `/ c. M7 I5 Q/ u8 Q3 S* a# }
  38.     in3 = *pSrc++;
    ' ]: b- v: k3 K% M9 W  w# h: \% V
  39.     in4 = *pSrc++;2 k  G  O4 I# c; Q: H3 n: r
  40. ! B; S( A9 K" s; d
  41.     *pDst++ = (in1 > 0) ? in1 : (q31_t)__QSUB(0, in1);                                              (2)
    $ l$ X6 f. M# _: v% Z& {# ]2 H
  42.     *pDst++ = (in2 > 0) ? in2 : (q31_t)__QSUB(0, in2);
    ' s" w" j! z1 u
  43.     *pDst++ = (in3 > 0) ? in3 : (q31_t)__QSUB(0, in3);/ H7 Q5 }7 Y- O) K/ v
  44.     *pDst++ = (in4 > 0) ? in4 : (q31_t)__QSUB(0, in4);, l  m% L3 N+ e: }* H" P2 @
  45.   c: z8 R$ |! q  L5 K
  46.     /* Decrement the loop counter */
    1 r0 W3 O4 }8 d' P/ m6 M8 j3 n  s) }
  47.     blkCnt--;
    ; q- |% \' }6 j) M% e
  48.   }
    7 X/ }  b/ s3 t  _  d# h5 G

  49. ! I5 @/ @4 s/ G  k" T, r! ]
  50.   /* If the blockSize is not a multiple of 4, compute any remaining output samples here.    ' x' g2 y" A( d5 j) ]# \
  51.    ** No loop unrolling is used. */
    . W' n+ D' {/ ?7 |0 R2 Z4 @; G
  52.   blkCnt = blockSize % 0x4u;
    ; c3 y8 t% k6 W1 S$ _
  53. 2 W1 }/ k' Y6 D8 D
  54. #else
    " z) W, b" L9 x
  55. 5 h4 O. q& Q+ o9 R* b2 v0 L
  56.   /* Run the below code for Cortex-M0 */1 G2 J: D5 Z, X7 [& r' ]3 U* T
  57. 9 Q. ~! d% d- L9 z7 p& e/ ?
  58.   /* Initialize blkCnt with number of samples */6 [8 Q% _, W( S3 a6 G/ X% X% G
  59.   blkCnt = blockSize;
    0 O8 X+ F' O" a$ ?

  60. ) N- W0 t4 ^+ f1 D, ]# B
  61. #endif /*   #ifndef ARM_MATH_CM0_FAMILY   */
    4 ?/ E9 {+ ~- V  D" c0 _
  62. , o/ g& H0 _8 L& B
  63.   while(blkCnt > 0u)# ~" K, c) J$ B0 }9 W
  64.   {
    " }' T4 ?  e+ s- p
  65.     /* C = |A| */0 i" f' E1 S/ K  w. t$ o" B. @2 w+ V
  66.     /* Calculate absolute value of the input (if -1 then saturated to 0x7fffffff) and then store the results in the destination buffer. */
    4 f& J" O) t+ R1 @
  67.     in = *pSrc++;
    % j$ n( k$ p+ `) `- j$ X/ t0 A
  68.     *pDst++ = (in > 0) ? in : ((in == INT32_MIN) ? INT32_MAX : -in);! T3 u" K) O  c

  69. ! f4 ]3 c0 {# a
  70.     /* Decrement the loop counter */
    2 f) I4 c4 d# i$ b, U5 c2 z
  71.     blkCnt--;
    ) |- Y& @4 c3 H  e+ Z0 K
  72.   }
    ( U9 k( R# t% d! @+ s- b) M" b4 H

  73.   Q" q, Y9 i% H4 C6 N! K" m, Q
  74. }
复制代码
1. 这个函数使用了饱和运算,其实不光这个函数,后面很多函数都是使用了饱和运算的,关于什么是饱和运算,大家看Cortex-M3权威指南中文版的4.3.6 小节:汇编语言:饱和运算即可。
    对于Q31格式的数据,饱和运算会使得数据0x80000000变成0x7fffffff(这个数比较特殊,算是特殊处理,记住即可)。
2. 这里重点说一下函数__QSUB,其实这个函数算是Cortex-M4/M3的一个指令,用于实现饱和减法。
    比如函数:__QSUB(0, in1) 的作用就是实现0 – in1并返回结果。这里__QSUB实现的是32位数的饱和减法。还有__QSUB16和__QSUB8实现的是16位和8位数的减法。
8.1.3 arm_abs_q15
    这个函数用于求15位定点数的绝对值,源代码分析如下:
  1. /**    ; Z& p* {( }( g+ \
  2. * @brief Q15 vector absolute value.   
    & V: G9 R' y5 M! c! ~" j. W
  3. * @param[in]       *pSrc points to the input buffer   
    # L: E, W& {7 R) R7 W0 O+ `
  4. * @param[out]      *pDst points to the output buffer   
    % e3 _7 i8 M1 H0 u: x$ g
  5. * @param[in]       blockSize number of samples in each vector    $ F% d( y2 n  u' X( V
  6. * @return none.    6 @' K: h4 ]. h2 y8 \6 n: E, G
  7. *   
    ' J% |& [( Y3 M4 Q) d# l4 W- t7 u. E/ [
  8. * <b>Scaling and Overflow Behavior:</b>    $ E0 o+ `: w" u
  9. * \par   
    % d9 p# T  u: [0 g
  10. * The function uses saturating arithmetic.    , K6 W& v8 u* M2 R( |6 ^; f
  11. * The Q15 value -1 (0x8000) will be saturated to the maximum allowable positive value 0x7FFF.       (1)
    ! V. Y0 V% r1 e' Y0 v7 r9 g" R$ {* {
  12. */
    % Y0 x$ c; ]; E  T; V, u

  13. 2 V# z4 t, H. f! [% R7 b& S4 R* C
  14. void arm_abs_q15(& U: o6 K/ N  B1 T( r/ W$ s% m% n
  15.   q15_t * pSrc,5 r: p: C3 ^4 P# f* H
  16.   q15_t * pDst,( d  O- n* \, k) k
  17.   uint32_t blockSize)
    . ~" h9 Z* `' X' f% o7 U" v
  18. {
    8 C4 \, w& u: l5 `# P+ b$ ]
  19.   uint32_t blkCnt;                               /* loop counter */4 R% A& Z' g% d2 P* S

  20. * U7 P; T5 y+ ^& }
  21. #ifndef ARM_MATH_CM0_FAMILY% @( A! [  l  r3 F) O
  22.   __SIMD32_TYPE *simd;                                                                               (2)4 S7 T  ^$ l, b, G5 b
  23. * R6 r1 C# Q3 m" R
  24. /* Run the below code for Cortex-M4 and Cortex-M3 */2 n& Y3 s; o5 u: g
  25. + G1 o9 j$ a$ q  t5 g3 k
  26.   q15_t in1;                                     /* Input value1 */
    + a: w" j/ t/ R) U7 }
  27.   q15_t in2;                                     /* Input value2 */
    + \* Q3 V! B5 b5 C' T

  28. ' V* B9 C% q- t* m' O( |/ V

  29. - Y, }! E9 g1 V6 j( S
  30.   /*loop Unrolling */
    9 p' Y2 @7 `/ b$ V+ I6 I# v
  31.   blkCnt = blockSize >> 2u;
    ( r" x9 o/ \* C& S9 s  z% _2 u; D
  32.   f  T+ g5 {" [' D8 U
  33.   /* First part of the processing with loop unrolling.  Compute 4 outputs at a time.    8 D( d4 G9 l+ V- w) ^3 `
  34.    ** a second loop below computes the remaining 1 to 3 samples. */
    9 d3 t$ k1 v7 I9 c
  35.   simd = __SIMD32_CONST(pDst);                                                                       (3)
      U0 f# T# F' j3 M; f
  36.   while(blkCnt > 0u)
    9 S7 Y: x0 {4 ^* ?' v; @
  37.   {
    ( M1 N$ {. U5 |) m+ M# v
  38.     /* C = |A| */
      `" t/ f* ~. s
  39.     /* Read two inputs */' r, d) `' r/ z$ [
  40.     in1 = *pSrc++;
    ( Y( K! V5 [8 b! D
  41.     in2 = *pSrc++;1 `% E. O& e9 u6 p

  42. 3 U  U" G9 Y  v8 [' }% m  p) d! v1 m

  43. 3 U+ z5 e/ X% `" T4 W
  44.     /* Store the Absolute result in the destination buffer by packing the two values, in a single cycle */
    2 s# R: ^+ P- U
  45. #ifndef  ARM_MATH_BIG_ENDIAN
    % ]' X" ?- O* ~4 ?9 b( L
  46.     *simd++ =4 N+ Z5 D! }7 n+ r; T( {' g: p
  47.       __PKHBT(((in1 > 0) ? in1 : (q15_t)__QSUB16(0, in1)),                                           (4)" |- E" l  \- y, T
  48.               ((in2 > 0) ? in2 : (q15_t)__QSUB16(0, in2)), 16);
    + m' O$ Z3 ^6 t
  49. & g5 F! H# z& b- w, ]
  50. #else: S/ q: a; I5 i- ^& w. B
  51. " b( n. ^" o  G- j5 H* v7 H: D

  52. 9 _! @; ^: m' G7 X& m
  53.     *simd++ =
    7 K+ `" }, ^2 I9 p
  54.       __PKHBT(((in2 > 0) ? in2 : (q15_t)__QSUB16(0, in2)),
    - J9 p/ u6 s9 `3 p8 c
  55.               ((in1 > 0) ? in1 : (q15_t)__QSUB16(0, in1)), 16);
    + r; @# n6 V2 _1 @! O# w5 b

  56. 9 {7 E# B/ @' u" n0 ^7 u
  57. #endif /* #ifndef  ARM_MATH_BIG_ENDIAN    */) H3 ]0 D  H; s/ ]- s
  58. 7 y$ z  M5 s2 z* w
  59.     in1 = *pSrc++;7 O, S. ~6 s7 Y2 [! i$ O8 P
  60.     in2 = *pSrc++;, `" W$ G7 ]( o3 V  L! F7 ^

  61. : I5 k, [! u9 i( y3 |  d5 i! z( ]

  62. : ~# W& o, R$ _( j# n  e( h# X
  63. #ifndef  ARM_MATH_BIG_ENDIAN
    ; v2 V; ]1 d+ b( ]" N9 y& a

  64. 6 ?1 x2 p' F1 y% f) w
  65.     *simd++ =7 F2 Q0 t: R( V! x' n) S% q5 \8 ]
  66.       __PKHBT(((in1 > 0) ? in1 : (q15_t)__QSUB16(0, in1)),* w. Q( r- k9 o3 {
  67.               ((in2 > 0) ? in2 : (q15_t)__QSUB16(0, in2)), 16);
    6 l+ X5 u8 _0 O, B" T  N
  68. 7 @' q; X- |9 ~" h5 @; h( ?
  69. #else
    4 Y8 Y/ t9 J* A0 H! o. R1 ^
  70. 1 i7 Q0 _& [; Q7 ]4 J" b/ G8 r
  71. % q7 g$ B8 B! |/ B
  72.     *simd++ =$ U2 S- {' G$ {  X
  73.       __PKHBT(((in2 > 0) ? in2 : (q15_t)__QSUB16(0, in2)),
    ( e6 o& V1 m. @  O8 I; u% d* }
  74.               ((in1 > 0) ? in1 : (q15_t)__QSUB16(0, in1)), 16);/ _: Y/ f/ E) M" E4 m! I- e1 y0 n

  75. / j! W. a  k8 T3 ~$ k& N
  76. #endif /* #ifndef  ARM_MATH_BIG_ENDIAN    */
    9 w8 }+ ?& @2 l* U

  77. 3 _1 N' z( z& r& r* M, z( R
  78.     /* Decrement the loop counter */; x. v9 ]( v0 s/ d  z& W9 m
  79.     blkCnt--;
    8 p) b, f1 w& L. ?+ u4 ^0 N* S
  80.   }0 Q: H% R, @$ N5 i7 |, B9 B
  81.   pDst = (q15_t *)simd;- `, b; B; I0 K3 x" |: v
  82.   /* If the blockSize is not a multiple of 4, compute any remaining output samples here.   
    * h& H1 R- b0 v9 i2 s2 Z& E
  83.    ** No loop unrolling is used. */- S- j9 I  U8 u) \
  84.   blkCnt = blockSize % 0x4u;7 @/ i1 V: ^+ P/ B& t# L
  85. 6 _2 Q4 v- E" R- S) n1 `
  86.   while(blkCnt > 0u)
    : |5 T7 y7 j: M$ V4 n& j
  87.   {. x. M- Z/ Q# n: L" k
  88.     /* C = |A| */
    : a) y, R: m! \: ]% q7 x) v4 U+ I0 N
  89.     /* Read the input */1 J7 `. H% c5 R* K; d# k/ E. \
  90.     in1 = *pSrc++;% C6 ~/ T; F' ?# D. W3 ]
  91. : s0 \) }4 d# K6 s& u
  92.     /* Calculate absolute value of input and then store the result in the destination buffer. */( ~, [3 ?0 h3 H2 s9 L5 ^
  93.     *pDst++ = (in1 > 0) ? in1 : (q15_t)__QSUB16(0, in1);
    " V: l% K2 u0 r

  94. 2 `' B. n6 a0 w1 p% f
  95.     /* Decrement the loop counter */' i/ S: M7 q6 j9 I% ^3 ]$ }
  96.     blkCnt--;
    % H2 {! a- i3 N& F, l! ~6 _
  97.   }3 H/ R1 f' A% l6 C! _. Q$ k
  98. & U5 q8 q; l3 E4 l: g! j% I$ G
  99. #else: n) X/ y! ~: E+ l( C# O
  100. / w- x0 V( ?% V( a6 o
  101.   /* Run the below code for Cortex-M0 */; w1 G8 K6 Z6 T+ p7 ]4 r2 P" ^0 G
  102. 6 _4 o& C, M& s- f
  103.   q15_t in;                                      /* Temporary input variable */4 K6 r& }2 Q. P/ N  ?) Q8 P# d. K

  104. + f7 F6 R, K/ \8 ?6 j0 r6 L( ^: Q
  105.   /* Initialize blkCnt with number of samples *// y; P$ d$ d. @% P
  106.   blkCnt = blockSize;& C( J# {, `1 l  _: ^( w
  107. 0 X6 [+ A4 [2 [8 i  ^1 l- S; d
  108.   while(blkCnt > 0u)* g9 D% s# }, B" y
  109.   {: S& J7 Y& ?5 O
  110.     /* C = |A| */9 E4 S7 k4 Z* i# n
  111.     /* Read the input */
      z) z5 l$ X/ q$ B3 {$ p0 R
  112.     in = *pSrc++;3 h, K* C4 r6 g. R& W

  113. * K" Z  w) @. k, d- H/ Y6 R
  114.     /* Calculate absolute value of input and then store the result in the destination buffer. */9 x6 N3 v# r# x; T' `( E( m/ F) Y
  115.     *pDst++ = (in > 0) ? in : ((in == (q15_t) 0x8000) ? 0x7fff : -in);
    / m4 ?6 N3 w9 z: D
  116. 7 ^; x5 [- g% j# R+ R2 ]
  117.     /* Decrement the loop counter */
    4 s  g: v; C7 ~" v& o) j$ J
  118.     blkCnt--;6 D  ~- R  @3 e0 R
  119.   }' {% H& |+ [" y1 q' U- l* W  i2 d

  120. , \' H, t) E& W
  121. #endif /* #ifndef ARM_MATH_CM0_FAMILY */
    7 \( n' T' l5 A1 ]" ~9 |
  122. ! H9 a( j0 h* a% U% t  |5 |* B
  123. }
复制代码
1. 对于Q15格式的数据,饱和运算会使得数据0x8000变成0x7fff。
2. __SIMD32_TYPE的定义在文件arm_math.h中,具体定义如下:
        #define __SIMD32_TYPE int32_t __packed
    SIMD就是咱们上期教程所将的单指令多数据流。简单的理解就是__SIMD32_TYPE就是定义了一个int32_t类型的数据,__packed的含义就是实现字节的对齐功能,方便两个16位数据的都存入到这个数据类型中。
3. 函数__SIMD32_CONST的定义如下:
    #define __SIMD32_CONST(addr)  ((__SIMD32_TYPE *)(addr))
4. 函数__PKHBT的定义在文件core_cm4_simd.h,定义如下:
    #define __PKHBT(ARG1,ARG2,ARG3)   ( ((((uint32_t)(ARG1)) ) & 0x0000FFFFUL) |  \
                                                          ((((uint32_t)(ARG2)) << (ARG3)) & 0xFFFF0000UL) )
        这个宏定义的作用就是将将两个16位的数据合并成32位数据。但是有一点要特别说明__PKHBT也是CM4内核支持的SIMD指令,上面的宏定义的C函数会被MDK自动识别并调用相应的PKHBT指令。
        __QSUB16用于实现16位数据的饱和减法。
8.1.4 arm_abs_q7
    这个函数用于求8位定点数的绝对值,源代码分析如下:
  1. /**        % d* F  w! n3 P* a
  2. * @brief Q7 vector absolute value.        
    6 h0 E2 F; D8 b3 W: n
  3. * @param[in]       *pSrc points to the input buffer        , S$ y8 x# c- R+ \( ?/ S1 s
  4. * @param[out]      *pDst points to the output buffer        
    . |4 b9 R& Q+ T( N* |% ^
  5. * @param[in]       blockSize number of samples in each vector        
    $ u3 p$ [1 n0 ]8 R2 C
  6. * @return none.        
    3 j( o% k; `* }, G) W
  7. *    & Z+ a2 R; ~* q  T, V! @2 j3 T$ n
  8. * \par Conditions for optimum performance   
    " C; z" d7 m& w5 d  L6 o
  9. *  Input and output buffers should be aligned by 32-bit   
    , {* B' R6 C# s$ u  H! C
  10. *   
    , `9 W1 d/ w. q7 S# j
  11. *        
    . e4 [6 g: A7 u" i/ n& _
  12. * <b>Scaling and Overflow Behavior:</b>                                                             (1)
    ( M, o/ G& j4 O8 ^1 h- h! L$ a
  13. * \par        ) ?/ |& h6 e) U: K; c& Z' ^( r
  14. * The function uses saturating arithmetic.        # o1 k7 w( E: D9 g
  15. * The Q7 value -1 (0x80) will be saturated to the maximum allowable positive value 0x7F.        
    + T8 Z, p, Q) r/ i4 C
  16. */* q' z4 g& f/ ]( d9 v# z
  17. 4 V! W3 [; Q8 p
  18. void arm_abs_q7(
    7 ^8 g  U- a) ~
  19.   q7_t * pSrc,2 w+ J8 `3 K' |; |; q# c
  20.   q7_t * pDst,
    . R0 v, f7 Q+ q  ]
  21.   uint32_t blockSize)" v' V5 j) L: j) F3 {7 O' Z
  22. {
    ) A+ z1 `, K1 r! {- b
  23.   uint32_t blkCnt;                               /* loop counter */2 `6 k2 K9 c- }
  24.   q7_t in;                                       /* Input value1 */
    # G6 ~  g. r( \
  25. ' p  m5 T6 ~  W* s1 B
  26. #ifndef ARM_MATH_CM0_FAMILY( X" s- r+ R' Z+ b: J0 Q

  27. " V/ H- O3 }+ S+ Y
  28.   /* Run the below code for Cortex-M4 and Cortex-M3 */$ k) U) ]; Q- }: N
  29.   q31_t in1, in2, in3, in4;                      /* temporary input variables */
    $ ^/ d$ n" N0 O' v
  30.   q31_t out1, out2, out3, out4;                  /* temporary output variables */
    9 R0 p' @# F+ p0 G2 c5 C' H+ \

  31. ' T' p. Z3 I% M, q1 u& G
  32.   /*loop Unrolling */! q* p9 ?1 u2 a, A* L9 e- v+ Z
  33.   blkCnt = blockSize >> 2u;
    9 _( z3 A1 _% {; n

  34. ! Y: r6 y5 T6 N. N
  35.   /* First part of the processing with loop unrolling.  Compute 4 outputs at a time.    / t+ f: p0 p8 p: E- H0 |
  36.    ** a second loop below computes the remaining 1 to 3 samples. */9 |* g6 X2 h  j( \- U0 G
  37.   while(blkCnt > 0u). H' q/ i( _' p9 ]- |& A. a
  38.   {1 a+ N2 F( _! o- l1 d5 p9 `
  39.     /* C = |A| */' A& S0 _0 _0 i7 t8 B* ]! s0 b' T( a
  40.     /* Read inputs */
    ; _/ B- j5 D2 i; U8 J; G) S
  41.     in1 = (q31_t) * pSrc;
    6 F  ~5 o$ k0 H  Y
  42.     in2 = (q31_t) * (pSrc + 1);1 b- ~9 ~1 B; @2 @5 t; W
  43.     in3 = (q31_t) * (pSrc + 2);
    6 v, Z2 m7 k5 h1 S
  44. 0 a6 {9 S4 D$ f8 C0 h
  45.     /* find absolute value */
    / |# U, H9 ~5 A3 V0 O
  46.     out1 = (in1 > 0) ? in1 : (q31_t)__QSUB8(0, in1);                                                  (2)
    1 x1 s. _0 \  `2 {

  47. % r* K7 Z( z) ~
  48.     /* read input */
    9 m2 [9 U! T) v# ?. l
  49.     in4 = (q31_t) * (pSrc + 3);) V0 v) ?2 k$ A' d! [& y2 t
  50. ) k3 a1 a1 c! E* n
  51.     /* find absolute value */
    3 B1 U  k7 V  N! i7 k
  52.     out2 = (in2 > 0) ? in2 : (q31_t)__QSUB8(0, in2);+ }  f3 x* }( V5 @- ^& {
  53. ! }6 Y3 O! K2 `" c
  54.     /* store result to destination */
    % e- G# ^6 \0 R) f& b0 {  J
  55.     *pDst = (q7_t) out1;
    + N$ n2 D& |2 h: ?& X& n. A" G
  56. ' f7 o( h' Q2 ]5 z/ @
  57.     /* find absolute value *// ?% V: d. q' y2 u& G% w& Z. l
  58.     out3 = (in3 > 0) ? in3 : (q31_t)__QSUB8(0, in3);0 u9 c: W2 f* X: e; j" ?0 p7 C

  59. 3 `+ X8 Z3 F; @
  60.     /* find absolute value */
    4 i6 G& l5 r' h5 @
  61.     out4 = (in4 > 0) ? in4 : (q31_t)__QSUB8(0, in4);
    ) a$ J1 G4 L+ A( e* P: \* C* T
  62. % V" Q5 R! N4 @5 ~7 H2 X$ X
  63.     /* store result to destination */
    / y9 i  N7 j0 C( F6 N/ R* \2 l1 t
  64.     *(pDst + 1) = (q7_t) out2;
    ; `( H! W' O6 p/ J& S
  65. 1 d2 M. P8 |  C2 L0 y. F
  66.     /* store result to destination */; n' }9 y2 m9 c& j6 Q( W
  67.     *(pDst + 2) = (q7_t) out3;* O% _3 N2 R8 r

  68. , ~2 v( r# E1 K
  69.     /* store result to destination */
    : G$ X' e* z, B1 x2 D; _. d9 |( M- {
  70.     *(pDst + 3) = (q7_t) out4;
    1 X. F6 u" Q# q

  71. 7 X* g5 L% ?; D
  72.     /* update pointers to process next samples */
    3 j' @: B/ m- h) x. J  ^+ p% W
  73.     pSrc += 4u;! i" _9 o6 n# \( l  C6 Y
  74.     pDst += 4u;- u4 r. }- L' k/ q

  75. : ^& W* v. X7 W& Q) ]; z
  76.     /* Decrement the loop counter */& ?  B. r  a# i. w0 u- g# V
  77.     blkCnt--;
    , F" V- N5 P& P, I
  78.   }
    4 T0 l+ ^0 P+ L) ?/ w* x; |0 Z2 _
  79. 7 N# F1 I# e' F6 O2 I. N
  80.   /* If the blockSize is not a multiple of 4, compute any remaining output samples here.    * n9 W5 e8 }; ^* A& j. ?
  81.    ** No loop unrolling is used. */
    " D$ m# d1 @6 b6 {- \7 [
  82.   blkCnt = blockSize % 0x4u;9 C: R& a  c( B5 I) @
  83. #else# d" F2 ~! ^& k! L7 q
  84. ! z+ U: l9 F& i' {( }* B7 l
  85.   /* Run the below code for Cortex-M0 */0 {9 m* Z9 E4 {) A) U
  86.   blkCnt = blockSize;) _- b% ~3 k) {' J7 U8 F1 [

  87. 7 j+ j' N- L0 O* K, [6 l& M
  88. #endif //      #define ARM_MATH_CM0_FAMILY) L/ k, }% [- ]6 ]0 s

  89. + T* T' Z. o6 c  X' ]" B9 g
  90.   while(blkCnt > 0u)
    8 X! o' W3 c9 @: R* c. o
  91.   {
    , c% T9 x& j2 }
  92.     /* C = |A| */5 W, T; |+ g' v$ Q1 U
  93.     /* Read the input */0 Q; g+ D1 f9 _; J: @4 R
  94.     in = *pSrc++;
    & j0 q& Y0 }0 {0 r4 E1 x

  95. 0 T/ y. S- P. l1 B: S& w, @, i, `
  96.     /* Store the Absolute result in the destination buffer */+ y0 ?! _( p3 x" O4 X
  97.     *pDst++ = (in > 0) ? in : ((in == (q7_t) 0x80) ? 0x7f : -in);
    3 l3 S" G! Y: q

  98. ! J+ }6 j* q2 @/ V$ A
  99.     /* Decrement the loop counter */
    ' _8 H7 Q! R1 O2 L7 P/ Q' e# F
  100.     blkCnt--;
    # k) r9 T6 I0 r$ c+ _4 P0 B2 `
  101.   }
      o% t! k+ t+ l
  102. }
复制代码
1. 由于饱和运算,0x80求绝对值将变成数据0x7F。
2. __QSUB8用以实现8位数的饱和减法运算。
8.1.5 实例讲解
实验目的:
    1. 四种数据类型数据绝对值求解
实验内容:
    1. 按下按键K1, 串口打印输出结果
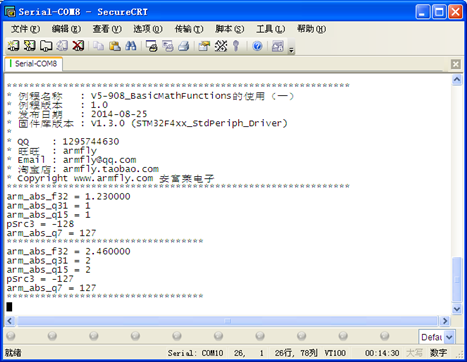
实验现象:
        通过窗口上位机软件SecureCRT(V5光盘里面有此软件)查看打印信息现象如下:
8.1.png
程序设计:
  1. /*
    8 s* ]; c! h2 D: ]  R' x
  2. *********************************************************************************************************. \) R4 G, i7 E  W, s5 j2 }. O
  3. *        函 数 名: DSP_ABS
    4 R5 u( d! I; X1 p/ T1 l2 Z  @6 c- E
  4. *        功能说明: 求绝对值9 t( C2 M) U9 }8 h8 S' t/ V/ p+ W
  5. *        形    参:无+ l$ X+ w4 a/ L
  6. *        返 回 值: 无
    3 S! t9 \5 z" C$ j/ }! m
  7. *********************************************************************************************************$ W% h$ Y4 q1 \: c5 P6 q! s
  8. */2 y; L: ~7 x; n
  9. static void DSP_ABS(void)$ P% z' f2 v6 p! A/ g
  10. {
    " i  T7 W- ]7 ]+ K2 ?8 g( ^  Z
  11. static float32_t pSrc;
    ; H8 C( X  `  N1 O
  12.     static float32_t pDst;
    : `, ]! M8 f, r8 B( U! m
  13. static q31_t pSrc1;, K8 J5 P& C1 k6 G, l' m- N1 u* l
  14. static q31_t pDst1;
    ; S: a4 `% E8 q: T6 ]7 H
  15. static q15_t pSrc2;; O9 E( |& o: P! e
  16. static q15_t pDst2;# w4 ?  Q+ `8 l. a
  17. static q7_t pSrc3 = 127; /* 为了说明问题,在这里设置初始值为127,然后查看0x80是否饱和为0x7F */" f/ T; @9 ~  H% j0 U8 [# o
  18. static q7_t pDst3;* T0 [$ N: H/ D! g* X
  19. pSrc -= 1.23f;( D+ V3 v) V' `, |
  20. arm_abs_f32(&pSrc, &pDst, 1);                                                                    (1)
    ' m% r7 I- i7 X2 d. v) ~
  21. printf("arm_abs_f32 = %f\r\n", pDst);
    ; r5 B3 {* I! i2 j6 `
  22. $ W1 s& {" j( k! P: [
  23. pSrc1 -= 1;
    & K3 @$ k5 W) Z- K! c2 o
  24. arm_abs_q31(&pSrc1, &pDst1, 1);                                                                  (2)
    $ D6 [0 N* g* @
  25. printf("arm_abs_q31 = %d\r\n", pDst1);2 h, ?0 i( D# J" T

  26. ! ?1 ~! h( q* k
  27. pSrc2 -= 1;" S0 H5 T* K6 t1 h3 C2 `+ J
  28. arm_abs_q15(&pSrc2, &pDst2, 1);                                                                  (3)
    + q9 M! O9 Q$ s
  29. printf("arm_abs_q15 = %d\r\n", pDst2);0 d& F3 ?- D2 e, T9 j9 C+ \% H

  30. 1 y# v; ?( |0 R. k! J% f  c
  31. pSrc3 += 1; + n. l2 _1 C6 ?0 U% g( W6 F% e1 P/ O
  32. printf("pSrc3 = %d\r\n", pSrc3);  |1 v( v" l, g7 T6 r1 P# t/ z3 F
  33. arm_abs_q7(&pSrc3, &pDst3, 1);                                                                   (4)
    7 l0 Y8 M" p9 O  y9 P! S! [8 Z
  34. printf("arm_abs_q7 = %d\r\n", pDst3);
    * }2 q; e: N6 _9 f
  35. printf("***********************************\r\n");: A9 Y. @5 A+ v/ B4 U; P9 p
  36. }
复制代码
(1)到(4)实现相应格式下绝对值的求解。这里只求了一个数,大家可以尝试求解一个数组的绝对值。
) C( p8 T" o' G& D4 `# z0 D
赞 收藏 评论5 发布时间:2015-3-18 11:33

举报

5个回答
baiyongbin2009 回答时间:2015-3-18 11:42:14
8.3 点乘(Vector Dot Product)
    这部分函数主要用于点乘,公式描述如下:
     sum = pSrcA[0]*pSrcB[0] + pSrcA[1]*pSrcB[1] + ... + pSrcA[blockSize-1]*pSrcB[blockSize-1]
8.3.1 arm_dot_prod_f32
    这个函数用于求32位浮点数的点乘,源代码分析如下:
  1. /**
    - @; a3 k7 l4 A% J( W5 V* {
  2. * @defgroup dot_prod Vector Dot Product
    . _( C" z0 A$ G. Z6 {
  3. *
    ) ?) ]3 A0 i3 m& i  u/ l
  4. * Computes the dot product of two vectors.1 ^- i2 g# W; ^6 b! {: ]: d/ Z/ e! O
  5. * The vectors are multiplied element-by-element and then summed.
    5 N; p3 w( S( O6 C( ]
  6. *+ C& g2 _& E% b. F) Y5 z6 e
  7. * <pre>+ W# m. o, W3 H
  8. *     sum = pSrcA[0]*pSrcB[0] + pSrcA[1]*pSrcB[1] + ... + pSrcA[blockSize-1]*pSrcB[blockSize-1]7 M8 w1 H' |- T$ R" e
  9. * </pre>     
    # U2 V$ n" k6 _; V
  10. *
    $ X2 @2 n; F2 L8 V
  11. * There are separate functions for floating-point, Q7, Q15, and Q31 data types.    0 k# h; z5 q/ y. Y  ]8 D
  12. */
    & m* O: o4 M7 r$ ?: n: G3 p

  13. 6 [$ J- |0 I3 y% a  {; Y0 P  Z
  14. /**    , x" r2 ?$ M0 e! `3 l% t' f0 y
  15. * @addtogroup dot_prod   
    + ?, Z: ~% r: B1 l! O+ S" h5 D
  16. * @{   
    3 q* ~1 t2 S, q6 K3 [
  17. */) \5 b& e- _4 Y7 H+ q9 b% `' U% A
  18. 5 K) x' g7 y; {" F& O4 ?
  19. /**    ) W$ P- C* r/ a5 f. ]
  20. * @brief Dot product of floating-point vectors.    * B0 |1 ^+ o: ^8 C8 G, W. W0 e
  21. * @param[in]       *pSrcA points to the first input vector   
    7 n9 S0 a8 o5 }6 e: Y, E2 w8 x
  22. * @param[in]       *pSrcB points to the second input vector   
    * Q" b4 L, M: w# n
  23. * @param[in]       blockSize number of samples in each vector    2 S0 ?8 B3 C" A. X5 _
  24. * @param[out]      *result output result returned here   
    ( _9 S7 b2 U2 r& S9 G5 b
  25. * @return none.   
    3 y1 Z% [  Y5 p# w+ _: S
  26. */+ X  A8 t: ^. W- @  `
  27. 2 c7 q7 P1 g+ v3 w5 L  E

  28. - X& w3 L  \! m! Z& C) g* |# R" M$ J3 _9 r
  29. void arm_dot_prod_f32(4 N  q" I. G2 z6 l# ?1 M
  30.   float32_t * pSrcA,
    ; ]) X( B9 o; n1 r- `+ k! f
  31.   float32_t * pSrcB,  l7 P; O' Z3 S9 R2 `
  32.   uint32_t blockSize,
    , c+ N9 e5 u' h- Q) _7 \) t
  33.   float32_t * result)/ Z; l1 e. c2 \8 L2 v
  34. {! I% K! ^$ ~& X6 n( l- Y
  35.   float32_t sum = 0.0f;                          /* Temporary result storage */                      (1)
    % Y" y; _! Z: C' y
  36.   uint32_t blkCnt;                               /* loop counter */
    8 [" Q! G/ X: M" s: K: w
  37. 9 o8 d( C" F; m" e0 L0 D
  38. / G; ~+ f3 R  j% b7 q1 k/ Y( d
  39. #ifndef ARM_MATH_CM0_FAMILY
    * t; E8 A4 h8 z- M  K6 S/ d5 }

  40. 5 L+ i# J2 p4 B
  41. /* Run the below code for Cortex-M4 and Cortex-M3 */9 Q, {- z: p3 i* H# _* T
  42.   /*loop Unrolling */
    & S! ~- r5 A/ [
  43.   blkCnt = blockSize >> 2u;
    - Z. R. o0 P* J  Q
  44. , e3 S& K/ l  J+ R& V
  45.   /* First part of the processing with loop unrolling.  Compute 4 outputs at a time.    6 ?- d3 R3 {# V, H
  46.    ** a second loop below computes the remaining 1 to 3 samples. */
    ) K1 J% y* l0 V7 @1 h
  47.   while(blkCnt > 0u)/ i9 \3 i2 P6 K' A  \( @
  48.   {
    % ~) y4 r5 m- k& c; ^
  49.     /* C = A[0]* B[0] + A[1]* B[1] + A[2]* B[2] + .....+ A[blockSize-1]* B[blockSize-1] */: {- n4 d" t& P1 q# x
  50.     /* Calculate dot product and then store the result in a temporary buffer */
      `* t# A# r) y7 f& d& E6 [
  51.     sum += (*pSrcA++) * (*pSrcB++);                                                                  (2)! m% {( U. X9 z
  52.     sum += (*pSrcA++) * (*pSrcB++);. ]4 K! {1 M5 {/ Q. |& e& L
  53.     sum += (*pSrcA++) * (*pSrcB++);3 Z1 d* w% f6 c7 I7 j
  54.     sum += (*pSrcA++) * (*pSrcB++);
    # Q: d% Y& |4 s5 l/ L

  55. , h1 Y( F' N( K( r9 @8 m
  56.     /* Decrement the loop counter */
    ; T) C' M. j# z" R- y1 w6 E8 F
  57.     blkCnt--;! c- \7 p1 @! z# d
  58.   }
    8 @# W" Y4 q/ K/ s

  59. 5 \/ G( O' D7 Y: o- B# h
  60.   /* If the blockSize is not a multiple of 4, compute any remaining output samples here.   
    8 x2 P) p, t8 N$ x& z4 R" w9 z
  61.    ** No loop unrolling is used. */
    " `) D( D3 g- I0 ^% S9 d9 a+ h
  62.   blkCnt = blockSize % 0x4u;& A) C) z) k  ]- h3 o

  63. ; V' O: g- f3 ]! u; X1 e( U' I
  64. #else
    9 Q, Y) f$ d0 R; n* Q9 ?7 d# q

  65. 2 s: t4 U8 J9 ^' R! i$ F& ]
  66.   /* Run the below code for Cortex-M0 */# ]; _" B3 r( V3 E, G; K7 k9 _

  67. ! V# r# N0 t/ M( D
  68.   /* Initialize blkCnt with number of samples */" s$ c  |+ J. V1 @* O& ?, e
  69.   blkCnt = blockSize;% l& J# I' o6 \7 D

  70. ; @/ `* }& [7 h& R% C
  71. #endif /* #ifndef ARM_MATH_CM0_FAMILY */
    ' E7 d3 N3 `1 j6 M

  72. ! d6 m" L: ?& ?* Z1 O* L% q

  73. 4 D& j& H& a& Y9 Q; B8 A" R6 K
  74.   while(blkCnt > 0u)7 K& k7 b7 x1 @; G! n
  75.   {) B, \7 ^1 d! V3 E# A! G
  76.     /* C = A[0]* B[0] + A[1]* B[1] + A[2]* B[2] + .....+ A[blockSize-1]* B[blockSize-1] */  k6 [; e5 T" r; q8 V! Y
  77.     /* Calculate dot product and then store the result in a temporary buffer. */) ^/ b( Q; N, L4 F# V
  78.     sum += (*pSrcA++) * (*pSrcB++);: }4 J6 C  p2 q* ^4 [3 S

  79. + y4 w: ^% g" X! s9 `  O
  80.     /* Decrement the loop counter */
    + E, ^5 k+ Q. c/ ^6 l
  81.     blkCnt--;* e1 l. v! \3 s3 }6 [
  82.   }
    ( {/ s1 i% n5 y  ^8 ^$ G" w% s6 S9 c$ p
  83.   /* Store the result back in the destination buffer */" G! r/ N) [  w
  84.   *result = sum;. \, }6 b0 \* R6 [6 N. p( j& L
  85. }
复制代码
1. 由于CM4上带的FPU是单精度的,所以初始化float32_t类型的浮点数时需要在数据的末尾加上f。
2. 类似函数sum += (*pSrcA++) * (*pSrcB++)最终会通过浮点的MAC(乘累加)实现,从而加快执行时间。
8.3.2 arm_dot_prod_q31
    这个函数用于求32位定点数的点乘,源代码分析如下:
  1. /**   
      g7 C7 m" Y/ ?# D+ E; b
  2. * @brief Dot product of Q31 vectors.    $ e+ l" w# N, Y% a: ]1 h! J0 h
  3. * @param[in]       *pSrcA points to the first input vector    ; H# c" X, s2 K- v% v, {
  4. * @param[in]       *pSrcB points to the second input vector   
    / }$ S: a7 W) f
  5. * @param[in]       blockSize number of samples in each vector    1 V" T& E% |+ `' y
  6. * @param[out]      *result output result returned here    ! B& X% v1 `) d+ b# `
  7. * @return none.    3 d0 G3 S% g' z5 i9 Y+ Q$ D
  8. *   
    9 [7 T. C) s$ e& w7 q7 Z9 `* k6 j
  9. * <b>Scaling and Overflow Behavior:</b>                                                              (1)
    # n; e8 t4 a' y( j
  10. * \par   
    0 A2 ^% Y+ T( l. W
  11. * The intermediate multiplications are in 1.31 x 1.31 = 2.62 format and these    $ V! @6 s5 \- ]' |5 E
  12. * are truncated to 2.48 format by discarding the lower 14 bits.    ; d5 j2 I/ q! Q6 e5 \7 l' f
  13. * The 2.48 result is then added without saturation to a 64-bit accumulator in 16.48 format.    9 M" v3 B% ?5 D+ u1 N$ g
  14. * There are 15 guard bits in the accumulator and there is no risk of overflow as long as    5 V5 @7 s% P' m+ Z' Y
  15. * the length of the vectors is less than 2^16 elements.    $ v. l& q- X( {8 b; \. o; D& e
  16. * The return result is in 16.48 format.   
    ! F! n9 E+ g! N: D4 O- c5 a, Q
  17. */
    4 v- a, d$ O. v+ w; j2 w
  18. " W# v* N5 n; P7 O9 b# _9 b
  19. void arm_dot_prod_q31($ y( B$ d2 }% N$ S- O* Y
  20.   q31_t * pSrcA,
    ) h  {+ x8 S; [
  21.   q31_t * pSrcB,$ r' o9 r/ U) k; g4 Q0 s2 P: ~
  22.   uint32_t blockSize,. K& u2 q1 r4 i% ]  S
  23.   q63_t * result)9 I# K4 A  m& ?3 b4 P. P
  24. {
    : e9 o- y$ i0 N! d: i' k
  25.   q63_t sum = 0;                                 /* Temporary result storage */
    0 c- R0 ^* I. `
  26.   uint32_t blkCnt;                               /* loop counter */  O6 Y# A, B( v3 b& k& ~; M7 X

  27. % N1 m; h  p5 Y. E7 Y0 j5 q3 ?
  28. - Z# r" l( {/ g! r0 W" [0 u
  29. #ifndef ARM_MATH_CM0_FAMILY( V- |4 _. }9 T1 Q# p) z( [
  30. ( H6 q* H! d; v$ @; ^# {- I5 \' Y
  31. /* Run the below code for Cortex-M4 and Cortex-M3 */
    & S% U# L0 ~: u" X8 I/ G
  32.   q31_t inA1, inA2, inA3, inA4;
    . f9 X& ^- R! F" H
  33.   q31_t inB1, inB2, inB3, inB4;( ~$ }4 B) @5 X1 T4 ^$ R# B) u
  34. 3 ]& C5 i+ {- f$ n( t+ ^
  35.   /*loop Unrolling */
    9 Z, W% |/ ^8 b' ~0 }/ |1 h
  36.   blkCnt = blockSize >> 2u;8 L' c0 g  [1 ~: A% i% |* D* p

  37. 5 u& j2 M; E9 M! r, k6 o
  38.   /* First part of the processing with loop unrolling.  Compute 4 outputs at a time.   
    9 O0 @: C7 L. H0 j! q3 S
  39.    ** a second loop below computes the remaining 1 to 3 samples. */
    * P% x* C! d* M' S
  40.   while(blkCnt > 0u)
    7 B0 x4 l, N  T1 i( [+ t& H" \
  41.   {
    ; X- {1 s. h$ A9 B6 O0 Q6 Y
  42.     /* C = A[0]* B[0] + A[1]* B[1] + A[2]* B[2] + .....+ A[blockSize-1]* B[blockSize-1] */
    + H3 V" |& g' ~/ {
  43.     /* Calculate dot product and then store the result in a temporary buffer. */: h! G0 Y5 P7 X( h7 O
  44.     inA1 = *pSrcA++;
    0 k  [0 P& a- [& W  Z
  45.     inA2 = *pSrcA++;; {4 ~/ ?6 c( N  L9 T
  46.     inA3 = *pSrcA++;
    , d9 U; ^. W, p+ g$ U! |! f
  47.     inA4 = *pSrcA++;
      n$ Q3 `( W% h1 s
  48.     inB1 = *pSrcB++;3 h$ c/ H% o5 H) f% \  l- V6 L
  49.     inB2 = *pSrcB++;0 u5 Y( A5 O" L) X* W
  50.     inB3 = *pSrcB++;
      H' A% w+ U* [* x
  51.     inB4 = *pSrcB++;' m$ ~" f% @) ]% r5 M5 r0 j# C4 Z: g

  52. 4 B- W# S% j% }
  53.     sum += ((q63_t) inA1 * inB1) >> 14u;                                                               (2)& i& @# d( H! E* ?- o  ~4 ]6 l. E
  54.     sum += ((q63_t) inA2 * inB2) >> 14u;
    3 w- V& c9 F/ Q9 q
  55.     sum += ((q63_t) inA3 * inB3) >> 14u;
    8 K4 F$ D$ I5 ^% ~! }
  56.     sum += ((q63_t) inA4 * inB4) >> 14u;
    # n$ _- M$ Y4 }9 v
  57. 6 G0 w' j4 Z8 w1 y7 i* z
  58.     /* Decrement the loop counter */
    5 q/ `4 P9 c$ x0 K: x$ H
  59.     blkCnt--;* K' X9 C; x" S% a6 G
  60.   }& p7 ]- Z6 X& ~' V# n

  61. 4 {0 c  v+ d& s/ b3 h
  62.   /* If the blockSize is not a multiple of 4, compute any remaining output samples here.   
    8 M4 P/ m. j% p9 g# w( Y: n) U
  63.    ** No loop unrolling is used. */
    2 Q% R, V& R6 {  f  W  y
  64.   blkCnt = blockSize % 0x4u;+ u$ O  u: w9 L2 S, [2 \* V% h' A

  65. + _4 M% p3 L' u. Y* M) V( ]
  66. #else9 k! y2 R7 b6 {% G
  67. 7 u; Y9 m; j! x' H# ?( W8 t. t1 X( \
  68.   /* Run the below code for Cortex-M0 */
    # @! I2 W0 L/ l9 w6 w% _
  69. / V- E0 G. r$ v: r3 s
  70.   /* Initialize blkCnt with number of samples */
    & S2 r0 k$ b$ p' P& I! ]1 a
  71.   blkCnt = blockSize;' z$ r- V( o, E
  72. ! n! o  Z. u  G' ]& s- u
  73. #endif /* #ifndef ARM_MATH_CM0_FAMILY */
    $ k! S3 R( s2 C
  74. , t7 M) {, L- [1 h" C. F
  75. 9 k* k' w. g7 ^. _2 v- r( v
  76.   while(blkCnt > 0u)7 J) W& t+ t# P. A1 H( V5 {
  77.   {
    ( b+ y7 ^7 |. ]  r/ `& b9 n
  78.     /* C = A[0]* B[0] + A[1]* B[1] + A[2]* B[2] + .....+ A[blockSize-1]* B[blockSize-1] */
    % D% A  Y/ ]  W5 S/ T# D
  79.     /* Calculate dot product and then store the result in a temporary buffer. */
    ' q& m+ }) K; p! i; g) V0 }& }
  80.     sum += ((q63_t) * pSrcA++ * *pSrcB++) >> 14u;
    " q& R1 i! `0 x* x9 m( ~

  81. - k3 C6 W8 R3 B- r
  82.     /* Decrement the loop counter */' J# q; l, E8 W' i' y, T
  83.     blkCnt--;: N' P1 _8 a& f! i$ N& g& E4 |. _# e
  84.   }
    . U& L: P" x+ R9 E9 D$ V

  85. % S4 ~0 j, U& e3 t, n
  86.   /* Store the result in the destination buffer in 16.48 format */
    9 p- m: z$ J* }9 n% f5 P
  87.   *result = sum;
    6 F5 ^& w" f: _3 ^2 a
  88. }
复制代码
1. 两个Q31格式的32位数相乘,那么输出结果的格式是1.31*1.31 = 2.62。实际应用中基本不需要这么高的精度,这个函数将低14位的数据截取掉,反应在函数中就是两个数的乘积左移14位,也就是定点数的小数点也左移14位,那么最终的结果的格式是16.48。所以只要乘累加的个数小于2^16就没有输出结果溢出的危险(不知道这里为什么不是2^14,留作以后解决)。
2. 将获取的结果左移14位。
8.3.3 arm_dot_prod_q15
    这个函数用于求16位定点数的点乘,源代码分析如下:
  1. /**   
    % }( z( ]7 m/ }4 `
  2. * @brief Dot product of Q15 vectors.    , \; ^. M- r, J7 N" ^& P
  3. * @param[in]       *pSrcA points to the first input vector    + e6 o; h8 o2 j* Y9 n
  4. * @param[in]       *pSrcB points to the second input vector   
    3 j+ f) n. P& }( r
  5. * @param[in]       blockSize number of samples in each vector    7 h6 B/ ^2 |; w! j
  6. * @param[out]      *result output result returned here    ' ~5 H, ]$ {) l4 @  E
  7. * @return none.   
    % Q, I+ m. z; r5 B
  8. *    ( {5 ?) h( y  {: x3 n
  9. * <b>Scaling and Overflow Behavior:</b>                                                             (1)$ ?+ n7 w% k7 v0 a% k& A% v0 l
  10. * \par    & k# M$ b! A( G, t8 ]/ L
  11. * The intermediate multiplications are in 1.15 x 1.15 = 2.30 format and these   
    ; i. N" f8 f' b
  12. * results are added to a 64-bit accumulator in 34.30 format.    4 S0 v! }! D8 A2 Y) j* T" a- M
  13. * Nonsaturating additions are used and given that there are 33 guard bits in the accumulator    . N. }; Y- c" B# g: l. g" e
  14. * there is no risk of overflow.   
    5 l5 t" w: v, n3 c6 p5 X1 [2 P+ a0 \
  15. * The return result is in 34.30 format.   
    . d- r& w5 V% n# A7 {. k1 W
  16. */
    0 O: E" _$ O: {0 l: |
  17. ' v' `0 x( a% k9 G- x8 G
  18. void arm_dot_prod_q15(
    & A1 ~! j' K9 B9 ~7 ^
  19.   q15_t * pSrcA,
    ' {2 a7 C( h1 {
  20.   q15_t * pSrcB,+ N) c5 f) D  X3 N* v+ c
  21.   uint32_t blockSize,
    # x$ t+ w& E7 X# a3 |/ K
  22.   q63_t * result)& a- C% ?4 o' F5 K: K2 a' R
  23. {
    ' b9 V5 W& v  }% Y$ |
  24.   q63_t sum = 0;                                 /* Temporary result storage */3 x. W9 l8 z1 ~* a2 U
  25.   uint32_t blkCnt;                               /* loop counter */9 Y& b2 G; L% `' {/ A
  26. ; d+ ^& f, Z8 P+ i
  27. #ifndef ARM_MATH_CM0_FAMILY
    # l) d  ~( Y3 p8 A7 K( V/ r  p

  28. 0 J& m8 L; v, o' @: K# C
  29. /* Run the below code for Cortex-M4 and Cortex-M3 */
    1 g/ q- M2 l: f  z
  30. 2 ]# I9 i  s  `; u8 _; t

  31. $ Z0 ^7 g/ R7 S
  32.   /*loop Unrolling */
    ' j/ R8 \$ u, ?$ F+ |: u
  33.   blkCnt = blockSize >> 2u;1 R" T+ C6 a" X; `3 X' ]% X) h1 u

  34. " l. @+ @# I) B3 R& i6 J
  35.   /* First part of the processing with loop unrolling.  Compute 4 outputs at a time.   
    ) n. j2 G" r4 |! f+ G) W, O0 k
  36.    ** a second loop below computes the remaining 1 to 3 samples. */
    4 `( \3 m* S/ K& U* x9 I$ C( ~- _
  37.   while(blkCnt > 0u)/ \7 U6 Y. c) k% M, O9 e1 z
  38.   {7 \' v7 B" o3 Y8 E$ L
  39.     /* C = A[0]* B[0] + A[1]* B[1] + A[2]* B[2] + .....+ A[blockSize-1]* B[blockSize-1] */           (2)
    $ r! T/ R5 {0 A. y$ G$ }5 X3 A
  40.     /* Calculate dot product and then store the result in a temporary buffer. */
    + H; c5 w, [1 s, V1 K* H
  41.     sum = __SMLALD(*__SIMD32(pSrcA)++, *__SIMD32(pSrcB)++, sum);
    # [5 |& w! x5 H9 M% q
  42.     sum = __SMLALD(*__SIMD32(pSrcA)++, *__SIMD32(pSrcB)++, sum);& w$ j6 [0 v) Q7 H9 B
  43. 7 j! H, c& m& L( p! y$ N! ^1 c. v
  44.     /* Decrement the loop counter */0 ^; e  D! R- o& C
  45.     blkCnt--;0 }9 `1 @0 k! n: H1 v
  46.   }
    . e: L$ q$ d) q4 I- X$ I' F/ R

  47. / M' z) E- I3 T8 p7 T  L6 a) H( C
  48.   /* If the blockSize is not a multiple of 4, compute any remaining output samples here.      [7 s7 _) m2 O  m* j0 H
  49.    ** No loop unrolling is used. */# f4 w) d4 x; J$ R* ^3 e
  50.   blkCnt = blockSize % 0x4u;
    0 ?6 ^# p" [! E& L& J2 X+ U

  51. ) Z8 y6 \9 H0 q* N/ p' {. a
  52.   while(blkCnt > 0u)
    6 |) y& D  M$ P2 Z: _4 {  l
  53.   {& E: I0 c  e4 H" l/ ]% t
  54.     /* C = A[0]* B[0] + A[1]* B[1] + A[2]* B[2] + .....+ A[blockSize-1]* B[blockSize-1] */0 r; {! ~4 ?2 @, m+ j
  55.     /* Calculate dot product and then store the results in a temporary buffer. */* @/ F' r& Y: E# C  f8 b" s- n. X/ t
  56.     sum = __SMLALD(*pSrcA++, *pSrcB++, sum);
    2 X  |3 ?" c5 }, N% X& ^4 i# z
  57. ! C  ^7 y3 R* u. y
  58.     /* Decrement the loop counter */$ S. w% V- M8 o1 o
  59.     blkCnt--;+ |/ ]4 Y6 x0 Z+ B; L4 L/ a0 D: O6 \
  60.   }
    4 M# m! O7 N' G# |7 ^+ Q$ r, [' A

  61. ( u+ c. Y$ A' v4 z! v' c
  62. + `) W8 u$ ^! G% O5 m
  63. #else7 e) s, M' Y/ a( l6 L- s

  64. ( I; i, G# c* l4 ]4 r0 ?6 U
  65.   /* Run the below code for Cortex-M0 */
    ' L0 {7 W8 ^" F% n* J6 R0 j$ M( X. o) F
  66. ; C4 C5 t" ~7 j1 t- {
  67.   /* Initialize blkCnt with number of samples */5 O  b! M* E' P$ D% A" D
  68.   blkCnt = blockSize;8 [7 ~' l) G: k' T

  69. , {1 l4 J, c, _/ B7 q1 N6 l
  70.   while(blkCnt > 0u)
    % S3 W+ v) k8 S# k* K, f
  71.   {$ O  n6 C3 ?& i6 \! ]! j! L, u9 r
  72.     /* C = A[0]* B[0] + A[1]* B[1] + A[2]* B[2] + .....+ A[blockSize-1]* B[blockSize-1] */' N! d# C8 F) J( \
  73.     /* Calculate dot product and then store the results in a temporary buffer. */6 e" T, ^& \! S+ }# }) f. X+ T
  74.     sum += (q63_t) ((q31_t) * pSrcA++ * *pSrcB++);
    ( Y' g" C5 N3 R+ l

  75. ( n3 K% @2 \1 p, O% v# X5 p; w
  76.     /* Decrement the loop counter */
    ; M5 a, y$ E( L2 P5 o+ o' _+ i+ w
  77.     blkCnt--;2 @! Q7 [0 T* S$ G3 [9 G
  78.   }
    $ u  H; F" g  T1 M

  79. : M( i" T& F8 _8 r' V
  80. #endif /* #ifndef ARM_MATH_CM0_FAMILY */
    6 u/ J) l) `9 ^+ g: K
  81. & B4 }- D. l$ _3 f. a
  82.   /* Store the result in the destination buffer in 34.30 format */$ L( v( w! ~1 b7 b) L
  83.   *result = sum;
    & V( v- A7 _6 ?& h1 D

  84. 7 `' i# N. H! N: q  U4 {
  85. }
复制代码
1. 两个Q15格式的数据相乘,那么输出结果的格式是1.15*1.15 = 2.30,这个函数将输出结果赋值给了64位变量,那么输出结果就是34.30格式。所以基本没有溢出的危险。
2. __SMLALD也是SIMD指令,实现两个16位数相乘,并把结果累加给64位变量。
8.3.4 arm_dot_prod_q7
    这个函数用于求8位定点数的点乘,源代码分析如下:
  1. /**    ; U. j5 {, Z) ?# g
  2. * @brief Dot product of Q7 vectors.    " {+ l) e% r! M+ e9 R
  3. * @param[in]       *pSrcA points to the first input vector   
    ( x! O2 U/ D1 c( k
  4. * @param[in]       *pSrcB points to the second input vector    ) b! O  p' O  P2 L" U% C- h
  5. * @param[in]       blockSize number of samples in each vector    # o5 {3 V. X3 {+ V  l
  6. * @param[out]      *result output result returned here    " q7 b: H8 @" Z3 P3 X+ c/ a
  7. * @return none.    8 H0 K2 l; X8 |* B' ^
  8. *   
    ( u- E) [: F+ z
  9. * <b>Scaling and Overflow Behavior:</b>                                                              (1)/ ^  O" M  R9 E; N& y* i
  10. * \par    ! a4 v2 F/ m) W) y, O1 t4 L
  11. * The intermediate multiplications are in 1.7 x 1.7 = 2.14 format and these    ' Q( X. T$ X8 j, _2 b) ]
  12. * results are added to an accumulator in 18.14 format.   
    7 @# R; W3 a" y( K* X% o
  13. * Nonsaturating additions are used and there is no danger of wrap around as long as    : C3 y9 ?4 B  A: a% ?4 L# M. S( S
  14. * the vectors are less than 2^18 elements long.   
    . X$ W3 ?- h: I) q
  15. * The return result is in 18.14 format.    7 j6 z( m7 O! s9 i# k
  16. */
      C4 ?) j8 e! h% l$ @
  17. - @9 a% w* c& w5 e7 B9 _1 N
  18. void arm_dot_prod_q7(
    4 n! k5 K+ t0 {3 o, T! V3 N
  19.   q7_t * pSrcA,
    5 Q9 ]9 g4 B5 _* w  a
  20.   q7_t * pSrcB,
    5 {. t9 z% C3 P1 I5 P. M
  21.   uint32_t blockSize,9 L1 j7 g" y4 \/ u
  22.   q31_t * result)
    1 l6 G, y6 ^' ]2 |: @- ~6 {
  23. {
    6 V+ \/ o$ O6 n: N6 Q& y; S. y% n$ c) \
  24.   uint32_t blkCnt;                               /* loop counter */
    8 M" ^* F0 b9 F( J! q3 ?9 D
  25. + F/ J" l1 p7 V! v) S) i. T
  26.   q31_t sum = 0;                                 /* Temporary variables to store output */
    $ m9 L9 V6 N+ d7 w0 R0 f" _

  27. 3 h8 m. [( N' h) S) j4 }- q, R7 z
  28. #ifndef ARM_MATH_CM0_FAMILY9 k$ ]* K* ]7 T; R* D: Y9 B
  29. ! m5 s" [2 [; C
  30. /* Run the below code for Cortex-M4 and Cortex-M3 */* N$ L+ Y0 n$ S+ {. H" z' |& [- O0 O

  31. 8 n# d7 c. D+ ~/ v. D/ B! S
  32.   q31_t input1, input2;                          /* Temporary variables to store input */
      H- i3 C2 K" n) s1 b. s4 S
  33.   q31_t inA1, inA2, inB1, inB2;                  /* Temporary variables to store input */" U8 }" m& K0 |" f+ l3 ]
  34. 6 \" r4 m% z$ T9 D0 Q3 v3 W1 s6 h
  35. & Y* J9 ?! W' i+ I9 ~

  36. ; i( A3 f+ [0 c  Y% u& Q3 r
  37.   /*loop Unrolling */8 }; m- V: V" `4 S; j9 i
  38.   blkCnt = blockSize >> 2u;
    ; D* K( h' M6 G  s0 q

  39. + N" D- I& z# C9 b- A
  40.   /* First part of the processing with loop unrolling.  Compute 4 outputs at a time.   
      b; |" f! y) F5 ^
  41.    ** a second loop below computes the remaining 1 to 3 samples. */
    . Q7 k+ {5 l4 I/ ?
  42.   while(blkCnt > 0u)
    ( }; x( R5 Q! Z
  43.   {# Q- @, N: _: O: |1 m: x7 n$ c
  44.     /* read 4 samples at a time from sourceA */                                                       (2)+ p9 C; _# Q' Y5 G" X
  45.     input1 = *__SIMD32(pSrcA)++;
    " d+ i+ m4 z+ C2 P% |
  46.     /* read 4 samples at a time from sourceB */$ _7 f: L: U0 l: `: j6 V
  47.     input2 = *__SIMD32(pSrcB)++;2 J. m) X* J& D6 F& C4 h1 u

  48. 0 c7 o! K, P! k  y
  49.     /* extract two q7_t samples to q15_t samples */3 h" A/ ~0 i3 U5 |  F
  50.     inA1 = __SXTB16(__ROR(input1, 8));                                                                (3)' X7 H$ S2 ]- H. \2 d: j+ O. {% a* ~
  51.     /* extract reminaing two samples */2 @) i* a, M* b+ G- o4 t
  52.     inA2 = __SXTB16(input1);
    . F6 u" i  k6 U' `/ T
  53.     /* extract two q7_t samples to q15_t samples */2 t  P/ j6 w+ M) N; @
  54.     inB1 = __SXTB16(__ROR(input2, 8));
    6 s" N2 l2 Z" _* q: s
  55.     /* extract reminaing two samples */
    2 L3 M; L7 M. N3 y5 E% X! [
  56.     inB2 = __SXTB16(input2);, O% ^6 p- j  G

  57. . L: |9 f% E3 s, h  Y; X. H+ `1 l) X
  58.     /* multiply and accumulate two samples at a time */
    / y' _, y/ h1 `; T# P
  59.     sum = __SMLAD(inA1, inB1, sum);                                                                   (4)
    5 N8 I' L# v( r9 |3 M/ Y
  60.     sum = __SMLAD(inA2, inB2, sum);% U, F" J$ M# {& x
  61. ( _" [3 h% R$ \1 v: o3 g
  62.     /* Decrement the loop counter */) _1 c, ~' n( q% ]
  63.     blkCnt--;
    $ _1 c" l4 ?6 o: |! n
  64.   }
    + g# b1 ^3 j% |
  65. . l4 f* i3 w) Z* Z) M' }
  66.   /* If the blockSize is not a multiple of 4, compute any remaining output samples here.   
    & u! a$ B  g( b( I+ \3 Q
  67.    ** No loop unrolling is used. */
    " R" T2 q; S' l4 f: a- q+ o
  68.   blkCnt = blockSize % 0x4u;% |; @2 @/ I) ^% a# h8 n

  69. . ?, ^2 d$ V6 E% v5 m$ [
  70.   while(blkCnt > 0u)
    & i" B" ]' `% k: N; h% Q4 o  A
  71.   {
      Q7 P: a7 E3 q; X8 L2 h$ k8 {2 z
  72.     /* C = A[0]* B[0] + A[1]* B[1] + A[2]* B[2] + .....+ A[blockSize-1]* B[blockSize-1] */+ i' {: m* U* C
  73.     /* Dot product and then store the results in a temporary buffer. */
    $ P; _8 R5 I: e! u
  74.     sum = __SMLAD(*pSrcA++, *pSrcB++, sum);
      _/ f6 O) V  f* M& ]) N

  75. . G' ]3 f# R$ {+ S1 {
  76.     /* Decrement the loop counter */
    " Z1 r4 G% L+ ^
  77.     blkCnt--;
    , b$ T" M' T) u; u* k
  78.   }
    7 q2 i- j' a& K, L& K
  79. , V; W/ H- b# E. B
  80. #else; O- _* {$ t4 F

  81. & S5 [* o- M, a2 f+ A
  82.   /* Run the below code for Cortex-M0 */
    2 ?3 t& F8 `# m

  83. ( S- Q* ?# @, k5 v2 G

  84. 1 ]! Z" Y& F! b( f! p/ n/ F$ E% B2 O

  85.   w9 L- W0 }' e
  86.   /* Initialize blkCnt with number of samples */
      V' c4 \) z4 ]" r/ L. c
  87.   blkCnt = blockSize;
    ! b5 W7 e* o( h+ h  L
  88. ! G% c' {4 y  ~* b  }6 e
  89.   while(blkCnt > 0u)! O& q: @1 @; M
  90.   {
    ! b0 q# }) J7 Y- F
  91.     /* C = A[0]* B[0] + A[1]* B[1] + A[2]* B[2] + .....+ A[blockSize-1]* B[blockSize-1] */4 P, {6 M# a5 @
  92.     /* Dot product and then store the results in a temporary buffer. */& W9 R/ {9 _# u- x( Q0 Q% D7 d" @
  93.     sum += (q31_t) ((q15_t) * pSrcA++ * *pSrcB++);; b4 e6 I/ t1 P& R

  94. / v- p3 u  b. m- J
  95.     /* Decrement the loop counter */
    3 L4 _$ J/ a) @9 a/ I
  96.     blkCnt--;+ S0 b5 X6 [% g3 D# @
  97.   }
    * c% A2 B/ F; n+ S+ S" ?: P) M- }

  98. 4 w1 j" p0 S: b2 b7 N
  99. #endif /* #ifndef ARM_MATH_CM0_FAMILY */
    0 v5 t. e" |1 M. S4 ^

  100. * q/ K! H( Y4 g6 f( e2 Z1 `( Q

  101. ; L3 ?- j3 s0 T% q" `$ F( r
  102.   /* Store the result in the destination buffer in 18.14 format */2 @  {, H& L* @( _1 y! _4 D/ E5 D# j
  103.   *result = sum;
    3 J% P& |3 {- [( `4 P/ J' {
  104. }
复制代码
1. 两个Q8格式的数据相乘,那么输出结果就是1.7*1.7 = 2.14格式。这里将最终结果赋值给了32位的变量,那么最终的格式就是18.14。如果乘累加的个数小于2^18那么就不会有溢出的危险(感觉这里应该是2^16)。
2. 一次读取4个8位的数据。
3. __SXTB16也是SIMD指令,用于将两个8位的有符号数扩展成16位。__ROR用于实现数据的循环右移。
4. __SMLAD也是SIMD指令,用于实现如下功能:
    sum = __SMLAD(x, y, z)
    sum = z + ((short)(x>>16) * (short)(y>>16)) + ((short)x * (short)y)
8.3.5 实例讲解
实验目的:
    1. 四种类型数据的点乘。
实验内容:
    1. 按下按键K3, 串口打印输出结果
实验现象:
        通过窗口上位机软件SecureCRT(V5光盘里面有此软件)查看打印信息现象如下:
8.3.png
程序设计:
  1. /*$ \. c% P9 a8 G. q5 S
  2. *********************************************************************************************************
    # A$ T. r8 i# }4 T  i- w- o0 R
  3. *        函 数 名: DSP_DotProduct
    ' Y4 F" t! w, [/ c( e" v
  4. *        功能说明: 乘积- R& D' c* [0 U% _  D1 r
  5. *        形    参:无
      `) V9 b: k' m' ^9 v+ r! _
  6. *        返 回 值: 无
    $ \) r- `! u9 l" ^- c! o
  7. *********************************************************************************************************
    . c0 w9 p+ c2 m
  8. */5 w# k/ [/ L/ g- ]# D
  9. static void DSP_DotProduct(void)
    5 ]& E- D+ @) y. u
  10. {% F  F) ~8 \1 s- q: p" I5 g
  11. static float32_t   pSrcA[5] = {1.0f,1.0f,1.0f,1.0f,1.0f};5 M4 T& a% A- A# f
  12. static float32_t   pSrcB[5] = {1.0f,1.0f,1.0f,1.0f,1.0f};  
    & z* O& k6 Z  F
  13. static float32_t   result;  
    6 b. P% x- `, s: E( U# H  l3 g
  14. static q31_t  pSrcA1[5] = {0x7ffffff0,1,1,1,1};  - |0 X3 U! j, Q" _7 Q, J9 u! i2 Y- q- Z
  15. static q31_t  pSrcB1[5] = {1,1,1,1,1};  
      T5 u2 Y8 C4 r+ B0 e! X! M; D
  16. static q63_t   result1;   
    ( f4 I8 d3 I1 l1 Y4 x3 r  F

  17. 4 M/ h* K' u- F/ [1 b8 d
  18. static q15_t  pSrcA2[5] = {1,1,1,1,1};  
    ) z, N* y5 Q0 k2 {' c
  19. static q15_t  pSrcB2[5] = {1,1,1,1,1};  : K+ G! {) p; u- q+ g& s& p
  20. static q63_t  result2;   7 U0 C# y* z& `+ ]- ?2 f) _) x

  21. 5 S- C2 s! T: Q; B1 P0 e. `
  22. static q7_t  pSrcA3[5] = {1,1,1,1,1}; 4 E# V/ L4 i5 h& M# J" Y# A7 k
  23. static q7_t  pSrcB3[5] = {1,1,1,1,1};  
    , F; H4 r' Q$ C! R
  24. static q31_t result3;  . M- }+ W5 h9 Q( V7 ]: k* j

  25. : t6 X5 {( c& W+ r! L
  26. pSrcA[0] -= 1.1f;
    ; Y0 [7 m0 S5 E- x
  27. arm_dot_prod_f32(pSrcA, pSrcB, 5, &result);5 A/ S& p' a. G- T  Q1 P, c
  28. printf("arm_dot_prod_f32 = %f\r\n", result);5 c7 g* h; S$ X$ t& L
  29. pSrcA1[0] -= 0xffff;
    ( S) L5 M+ P) h# w! I' E
  30. arm_dot_prod_q31(pSrcA1, pSrcB1, 5, &result1);8 V3 h$ \1 E; _! a/ d
  31. printf("arm_dot_prod_q31 = %lld\r\n", result1);  g  [" X9 c3 A5 n( Y1 I+ B! A

  32. , @7 R* E( b2 c( O8 j( L
  33. pSrcA2[0] -= 1;
    4 o% u' ]$ `0 G/ Q. o" _
  34. arm_dot_prod_q15(pSrcA2, pSrcB2, 5, &result2);
    3 M8 e! H" D5 y" U+ A2 Q: S
  35. printf("arm_dot_prod_q15 = %lld\r\n", result2);
    & p  N8 N. |6 h4 M, m2 Y! t
  36. 8 q; P7 i! M0 V) I; O
  37. pSrcA3[0] -= 1;( h8 G6 ]# n7 X2 r' b
  38. arm_dot_prod_q7(pSrcA3, pSrcB3, 5, &result3);
    3 I6 |8 |& s7 @7 y$ ~- [5 R
  39. printf("arm_dot_prod_q7 = %d\r\n", result3);! }7 I5 ?! Q( T" s
  40. printf("***********************************\r\n");
    $ ]; p; A- ^0 u( v# _4 a* A
  41. }
复制代码
3 G( O5 V. p) U# K
9 B. j- h8 O* Z4 P1 [! Q
baiyongbin2009 回答时间:2015-3-18 11:38:01
8.2 求和(Vector Addition)
    这部分函数主要用于求和,公式描述如下:
    pDst[n] = pSrcA[n] + pSrcB[n],   0 <= n < blockSize.
8.2.1 arm_add_f32
    这个函数用于求32位浮点数的和,源代码分析如下:
  1. /**        ( r* b- z4 Y) s# u8 {: R  r
  2. * @brief Floating-point vector addition.        ; U6 Q; y$ m* b3 @5 E% Y# t  U
  3. * @param[in]       *pSrcA points to the first input vector        
    ; e+ H8 p' F$ Y* {, s7 V
  4. * @param[in]       *pSrcB points to the second input vector        4 J2 c+ |; j, A: F5 i/ S
  5. * @param[out]      *pDst points to the output vector        
    % C& X! G* K0 }% s
  6. * @param[in]       blockSize number of samples in each vector        " Y. l# ^: `# [. c. [: D; W
  7. * @return none.        
    0 A( D9 @# ~6 k" m, F
  8. */( w" q7 o- j. C3 n
  9. % S" K1 e' |1 [$ L2 o$ f: O
  10. void arm_add_f32(* P4 R+ r; s* Y: w" Y/ k6 k0 A. T# F
  11.   float32_t * pSrcA,
    5 G+ L. H0 }- i( f0 W' Y
  12.   float32_t * pSrcB,
    : y4 h% a7 w+ G! d2 i7 c* P+ j
  13.   float32_t * pDst,5 ^4 U4 c9 T7 h- S1 Y7 w* R6 Y/ o4 C
  14.   uint32_t blockSize)
    : T# X  J& [- O/ h' C  x
  15. {
    2 n! M9 v& ]+ R8 y* K. v3 v
  16.   uint32_t blkCnt;                               /* loop counter */
    9 \) n0 s" A. J# y0 Q: E, d, \
  17. ' I  e3 R, G9 S& `2 r
  18. #ifndef ARM_MATH_CM0_FAMILY; m( y' C- R7 z1 ~- d) {. H; _

  19. - w( k5 e$ K' }: |" {  d
  20. /* Run the below code for Cortex-M4 and Cortex-M3 */: t& f/ p" X& _$ c; k9 n  v% ~
  21.   float32_t inA1, inA2, inA3, inA4;              /* temporary input variabels *// t! W, ~; [8 b) ?9 @& Q
  22.   float32_t inB1, inB2, inB3, inB4;              /* temporary input variables */% ]/ j, v. k6 s5 O$ Y% F$ Q6 `

  23. # Y3 z7 [9 V+ |% [* u8 b+ ^; P
  24.   /*loop Unrolling */
    7 z- q& B' c/ l+ k
  25.   blkCnt = blockSize >> 2u;
    4 l5 W  _3 |& F) a: }  w
  26. , E1 n, _/ s; x
  27.   /* First part of the processing with loop unrolling.  Compute 4 outputs at a time.        
    ; C' P6 L: G" Y+ R
  28.    ** a second loop below computes the remaining 1 to 3 samples. */
    . m+ |; t4 b$ G: y+ B: n# A3 ]& H
  29.   while(blkCnt > 0u)
    ' H  f& T! o. g' ]6 c" v, Z4 U2 `
  30.   {" @4 T' {/ i( J8 z/ Y. n: w
  31.     /* C = A + B */
    " V: k/ u; m" B* I4 U  m6 }/ P
  32.     /* Add and then store the results in the destination buffer. */
    : v5 B& Y+ `6 o8 M

  33. : O7 M, ~+ K  {0 h9 a
  34.     /* read four inputs from sourceA and four inputs from sourceB */
    ) `2 ]! D  f* y+ ]/ Q8 u: P$ E
  35.     inA1 = *pSrcA;
    3 z$ ^0 ~. c4 C# l$ t. J
  36.     inB1 = *pSrcB;1 b, E! g/ g/ P2 ~+ }+ G
  37.     inA2 = *(pSrcA + 1);7 q7 V& y- P; v9 Q2 i
  38.     inB2 = *(pSrcB + 1);. O; ]' P4 t# K! O2 D! B
  39.     inA3 = *(pSrcA + 2);
    6 ^2 T, U: O' ~3 d
  40.     inB3 = *(pSrcB + 2);4 o6 y" i5 ?( Z( \& l
  41.     inA4 = *(pSrcA + 3);
    ' e% `; c) _6 [) W
  42.     inB4 = *(pSrcB + 3);
    ' B5 [  J$ e% w9 R! O1 h! u
  43. + n3 b% X0 O. J: _$ K- a  s
  44.     /* C = A + B */                                                                                  (1)
    % F7 y5 L  K. {" T& o% @' v
  45.     /* add and store result to destination */
    9 v/ A* ?" Z& i, W3 S0 K
  46.     *pDst = inA1 + inB1;5 g; j: K! }! Q4 h9 T
  47.     *(pDst + 1) = inA2 + inB2;4 Q: e0 Q* m# t9 j; n% G
  48.     *(pDst + 2) = inA3 + inB3;
    3 \" F; Q/ C/ t/ s. Q( Q- L  t& p
  49.     *(pDst + 3) = inA4 + inB4;
    $ [5 T7 B6 F; V" q3 `& N
  50. ! O0 f$ U& Z0 ~; E2 c4 g
  51.     /* update pointers to process next samples */
    & R( [" W( B! p* p# i' k
  52.     pSrcA += 4u;1 x/ k3 Y& `+ d, {# |7 }0 [
  53.     pSrcB += 4u;; N( E1 c3 X) d% t5 L4 ?' f) i
  54.     pDst += 4u;' s5 ~9 O9 B$ W# [' o: K( s) H

  55. ! f2 ?. }: Q+ J  E2 c# @

  56. 4 ?/ G! C7 C1 D0 e& R7 M0 [' o
  57.     /* Decrement the loop counter */8 [" j) W* B6 ?; G& n
  58.     blkCnt--;
    ; Y% ?* q, g( O$ U
  59.   }
    ) H7 u- T  u+ P* R3 v

  60. 3 w4 [7 _, Q$ O+ i' G) u
  61.   /* If the blockSize is not a multiple of 4, compute any remaining output samples here.        
      o" \& M: T/ F% K+ d
  62.    ** No loop unrolling is used. */
    1 ^, Z/ y8 j) Q9 f! B
  63.   blkCnt = blockSize % 0x4u;3 X! F$ e% [/ X! o, n$ ^
  64. 8 B5 T, D$ ?5 f9 s4 J: Y
  65. #else
    3 Y, h, N4 U1 E

  66. " [7 l) X% e" v: w; l
  67.   /* Run the below code for Cortex-M0 */0 q$ V: ~. T& e

  68. 5 k5 ]1 R4 P0 p: W% ]
  69.   /* Initialize blkCnt with number of samples */
    ! t, {$ M, S& F5 u( q
  70.   blkCnt = blockSize;
    ' z9 U4 n, i' m/ O& w: r" {5 Q
  71. 8 S# c9 t% {( ^
  72. #endif /* #ifndef ARM_MATH_CM0_FAMILY */
    0 T) z& R1 e1 ^
  73. 1 b% z, }! A0 R9 g& W* _
  74.   while(blkCnt > 0u)6 i" Q! Z7 f* F- U) N
  75.   {5 H+ a" I& j9 {1 p
  76.     /* C = A + B */
    . `3 C* f8 y2 Z, g6 y
  77.     /* Add and then store the results in the destination buffer. */( H3 r$ X8 s/ D  B2 W6 `
  78.     *pDst++ = (*pSrcA++) + (*pSrcB++);* H& E! }' Q7 `
  79. ; u; F& R' }5 z& L' v- U0 U6 X9 ]) }
  80.     /* Decrement the loop counter */
    3 F+ [& w3 K, e# L0 x7 P$ t
  81.     blkCnt--;. N+ e$ @' t; n: E, s; o  U/ h
  82.   }& J0 p8 R# }# j: P
  83. }
复制代码
1. 这部分的代码比较简单,只是求解两个数的和。
8.2.2 arm_add_q31
    这个函数用于求32位定点数的和,源代码分析如下:
  1. /**    7 R+ R2 E$ l1 P# @
  2. * @brief Q31 vector addition.   
    6 p/ z* V& x8 |: N, G
  3. * @param[in]       *pSrcA points to the first input vector    5 Z9 e% K0 V& z4 `4 `9 w5 B* U
  4. * @param[in]       *pSrcB points to the second input vector   
    - m$ F* ?' n0 p6 Z
  5. * @param[out]      *pDst points to the output vector    4 d; B5 `, H2 G
  6. * @param[in]       blockSize number of samples in each vector   
    ' I! d: q5 d9 @. Z" a* q! N9 @+ A! o
  7. * @return none.    5 ~6 Z, e7 P- G, c% |5 J! a
  8. *    5 [/ a9 I! K6 H, [3 ^1 e
  9. * <b>Scaling and Overflow Behavior:</b>                                                             (1)
    ! A2 s2 |# O; ~" p: {
  10. * \par    ; h# J$ u0 x3 Y* k3 A: T, T2 W
  11. * The function uses saturating arithmetic.    $ n+ L' h( }! u: Z
  12. * Results outside of the allowable Q31 range[0x80000000 0x7FFFFFFF] will be saturated.    ) q. X+ C2 g. D% ]
  13. */) A  @" L7 h; ~+ ?! j8 L" i
  14. ! b; A( q8 Y& y! r) z2 f, W; o
  15. void arm_add_q31(
    8 ?) j- R3 K% R+ S$ D6 G
  16.   q31_t * pSrcA,7 {- t4 c4 Q0 d/ V# g
  17.   q31_t * pSrcB,- y. s2 j7 h7 N! Q; d7 J  ~) d
  18.   q31_t * pDst," `& ?) L4 O  N4 G+ K
  19.   uint32_t blockSize)& _( }4 ^" w9 `: r* @8 q: f
  20. {# Z5 w2 T1 I) J; V/ V- P! w
  21.   uint32_t blkCnt;                               /* loop counter */
    # i3 H" F3 n8 z' m) f! P
  22.   \8 |9 l' p4 U: {) \
  23. #ifndef ARM_MATH_CM0_FAMILY
    9 ^/ p# `! _  u
  24. ; n. X  w/ J6 Y
  25. /* Run the below code for Cortex-M4 and Cortex-M3 */" f+ q" k) I% {( p
  26.   q31_t inA1, inA2, inA3, inA4;
    ) m8 d6 z3 |) l9 u3 `, i/ N( y
  27.   q31_t inB1, inB2, inB3, inB4;
    5 |* ^, G4 E! l& _) y5 f2 f: s

  28. 8 O' k5 v- i; p9 n  C3 q8 C! S
  29.   /*loop Unrolling */
    / w8 p1 _, N- [2 [& r5 V( j
  30.   blkCnt = blockSize >> 2u;
    9 k: z0 A* v! w  _0 G9 ~, \
  31. % U0 D$ r3 K7 h* y
  32.   /* First part of the processing with loop unrolling.  Compute 4 outputs at a time.   
    6 L6 R6 l- d6 K* C
  33.    ** a second loop below computes the remaining 1 to 3 samples. */2 y8 `; e! @5 \* Y9 y1 t
  34.   while(blkCnt > 0u)9 p7 C: u$ m: M4 X+ W/ |
  35.   {
    3 F# }- K* I) M1 F7 o
  36.     /* C = A + B */
    ! D& ^+ e; f3 V3 v* K6 E: s
  37.     /* Add and then store the results in the destination buffer. */
    : r3 F( p3 u2 E) C5 x; i* S
  38.     inA1 = *pSrcA++;) u6 X1 K$ q$ J2 P$ M) t. y
  39.     inA2 = *pSrcA++;
    ( p0 X. V- D$ Q9 ]* t6 @5 L) P, Z
  40.     inB1 = *pSrcB++;* j. c1 {. a% ~8 Z- b+ h
  41.     inB2 = *pSrcB++;
    1 j0 I" B6 S. T% u
  42. 4 _6 K# ]+ z, G: e4 |8 L+ O
  43.     inA3 = *pSrcA++;
    ( @8 T% K  d) `( X' f( o
  44.     inA4 = *pSrcA++;7 j7 N" G5 k. D- p* C# k/ a
  45.     inB3 = *pSrcB++;2 K- p/ X- t/ L# J4 P! z
  46.     inB4 = *pSrcB++;
    / I7 j" h1 z9 R- h% u& V1 d" [
  47. - T  K$ u, l8 L0 x. P. \/ z
  48.     *pDst++ = __QADD(inA1, inB1);                                                                   (2)4 D. B: b7 S* a! q, ~& J, j
  49.     *pDst++ = __QADD(inA2, inB2);
    , W" h5 w1 H8 @) X6 M! s. p" L
  50.     *pDst++ = __QADD(inA3, inB3);
    , t$ t5 q! {& [0 ]4 H# {/ L# {; W
  51.     *pDst++ = __QADD(inA4, inB4);4 `0 ?0 q1 f% |4 f* i5 Y

  52. 2 `0 a9 x2 w1 L' t3 r" G! @
  53.     /* Decrement the loop counter */. |5 E: C4 c0 H( |4 x0 I- Y; U
  54.     blkCnt--;
    # ^: `0 c; V+ o: w% b: |- d
  55.   }5 \, N- ~  z3 q( v, _! B
  56. / G2 Y& k, u1 v+ ^% d
  57.   /* If the blockSize is not a multiple of 4, compute any remaining output samples here.    ; F9 f# p4 v8 e' n! y& \. M
  58.    ** No loop unrolling is used. */; Z4 y3 D  r( P* z7 u3 {% Z8 Z
  59.   blkCnt = blockSize % 0x4u;
    ! Z3 p" X3 d+ R1 ~; M

  60. 6 ?# ~7 B5 N3 O! D5 p
  61.   while(blkCnt > 0u)- `+ Z' S, h% _" n. z
  62.   {
    - e1 U! \* {1 A: y0 @# V
  63.     /* C = A + B */- E. C2 G. k7 q9 v8 w- {  V, j
  64.     /* Add and then store the results in the destination buffer. */, ^5 A3 G+ U. r/ J& f) J* X
  65.     *pDst++ = __QADD(*pSrcA++, *pSrcB++);
    , k, V6 N) w/ Z  m

  66. " {9 O" `, _7 L0 H  {3 ]
  67.     /* Decrement the loop counter */, P( X5 i5 g8 u% O% v1 W- G
  68.     blkCnt--;
    ) O) C# B- K" Q+ S
  69.   }
    - o. @- e# ?0 G+ \. j# a

  70. ! @# |1 M! d0 v
  71. #else- \* {$ s  [  W% x

  72. 0 {9 O: t4 \( `) G& Z$ n5 Q/ ?% |0 B
  73.   /* Run the below code for Cortex-M0 */- F" m- w+ k! b1 i; q- ?/ C" }. D

  74. ; G/ [* Q! Y3 J

  75. - a8 V, P, G- H* R& E
  76. : y# Y2 g/ m) o( p: ~" ^
  77.   /* Initialize blkCnt with number of samples */
    2 B" W1 p3 I7 v1 l+ `
  78.   blkCnt = blockSize;
    ) v' b2 t" |; C; H0 t, T
  79. 0 ~6 b, O! r) w5 |3 i
  80.   while(blkCnt > 0u)
    / A9 x' i9 w0 g; W; k$ _& g" U
  81.   {% T- D# w+ q# D  |  Y7 ^
  82.     /* C = A + B */" G+ @1 L! I6 D7 p8 x5 O
  83.     /* Add and then store the results in the destination buffer. */  |5 m. m$ r4 ^* N8 L
  84.     *pDst++ = (q31_t) clip_q63_to_q31((q63_t) * pSrcA++ + *pSrcB++);                                  (3)( a1 C, T6 c! }6 Y1 V" e* q4 k* `
  85. . p7 X3 R' i. _! E  C+ ?' D: @7 E' w
  86.     /* Decrement the loop counter */; h( d  C& _0 G: |9 g9 Z, a6 ^4 H
  87.     blkCnt--;
    ( m+ b" B8 ]2 f% a
  88.   }
    * v5 m0 @! w8 u1 {1 C1 V6 f: j
  89. # u* E. ~' k# y7 X' C% r
  90. #endif /* #ifndef ARM_MATH_CM0_FAMILY */
    0 F& H  t$ @( R  |9 c

  91. * |2 |1 Q5 O) f! f" I0 d
  92. }
复制代码
1. 这个函数也是饱和运算,输出结果的范围[0x80000000 0x7FFFFFFF],超出这个结果将产生饱和结果。
2. __QADD实现32位数的加法。
3. 函数clip_q63_to_q31的定义在文件arm_math.h里面
      static __INLINE q31_t clip_q63_to_q31(
      q63_t x)
      {
           return ((q31_t) (x >> 32) != ((q31_t) x >> 31)) ?
             ((0x7FFFFFFF ^ ((q31_t) (x >> 63)))) : (q31_t) x;
          }
    这个函数的作用是实现饱和结果。
8.2.3 arm_add_q15
    这个函数用于求16位定点数的和,源代码分析如下:
  1. /**   
    , G. t+ f+ b1 M9 _' i: G9 N/ a
  2. * @brief Q15 vector addition.    + a/ B' s+ [& I" M' `8 X
  3. * @param[in]       *pSrcA points to the first input vector    ; C. R( ^7 Z( z9 P- I7 d: X5 Y
  4. * @param[in]       *pSrcB points to the second input vector   
      z2 B* D$ u: g9 w+ J
  5. * @param[out]      *pDst points to the output vector    5 V7 S+ n0 l! c+ C3 `; H
  6. * @param[in]       blockSize number of samples in each vector   
    ' U3 `# v: e2 E0 e
  7. * @return none.    " b8 ?( J5 N4 ]6 o( n
  8. *   
    : o% t& y- M9 F0 _7 j/ @
  9. * <b>Scaling and Overflow Behavior:</b>                                                               (1)6 z3 j0 b' y0 ~7 _( o, B+ ^( l
  10. * \par    & D3 C9 R7 J4 |- m7 G5 V
  11. * The function uses saturating arithmetic.    , t. _4 j# @0 C' T8 Q( F
  12. * Results outside of the allowable Q15 range [0x8000 0x7FFF] will be saturated.   
    $ p# @3 l" t1 n* c1 Y2 P/ W# l
  13. */* {- B& {# C- P9 ^# W

  14. 2 L  P  d9 a" _" V: A7 D. r
  15. void arm_add_q15(& h3 w5 P0 n$ Z- p1 W* l
  16.   q15_t * pSrcA,# s: u9 n2 |0 ~9 n2 ~
  17.   q15_t * pSrcB,4 n1 u$ K4 P; r' |0 S, q2 ?
  18.   q15_t * pDst,# e" J0 d, u  E
  19.   uint32_t blockSize)1 Q7 w! T4 b/ }+ P/ P0 B, U
  20. {
    ( A$ n7 ^" h4 f+ Z
  21.   uint32_t blkCnt;                               /* loop counter */- \1 Y: P! }% d8 O' O, v* _" a

  22.   ]$ d( F& s, E1 C9 @0 d
  23. #ifndef ARM_MATH_CM0_FAMILY; H& J5 V: t* d. M* H, O

  24. 5 s, `2 m$ i6 Q+ a
  25. /* Run the below code for Cortex-M4 and Cortex-M3 */
    ; {- g# `* U+ w$ }* z, V, I& _
  26.   q31_t inA1, inA2, inB1, inB2;" h7 C) y( k/ R
  27. 0 t0 m' Y' }: p3 m
  28.   /*loop Unrolling */
    & t& N7 B7 l* V. j& f4 p; w
  29.   blkCnt = blockSize >> 2u;( ~, K: E) D( A9 l  m
  30. * p% ^! o1 X! t
  31.   /* First part of the processing with loop unrolling.  Compute 4 outputs at a time.    % Y  f$ o0 r( n4 Z
  32.    ** a second loop below computes the remaining 1 to 3 samples. */
    ; k2 `# ]- N& J' ^  ~, @
  33.   while(blkCnt > 0u)
    + \! n$ X& P- ~9 ?2 u( a
  34.   {+ p( c- P# m& v! U; D
  35.     /* C = A + B */                                                                                    (2)
    ' P$ q% D/ a8 m$ ?2 J; n/ J
  36.     /* Add and then store the results in the destination buffer. */% \& [) X/ A' k. V+ x
  37.     inA1 = *__SIMD32(pSrcA)++;
    5 O# d* h) _% T8 l- _
  38.     inA2 = *__SIMD32(pSrcA)++;
    ( M& N- {+ s( h* _5 ?2 S* x1 J+ }
  39.     inB1 = *__SIMD32(pSrcB)++;) }0 N7 S3 }$ }6 Z. ~* e+ x
  40.     inB2 = *__SIMD32(pSrcB)++;! h: C5 O8 k7 l' f5 x
  41. - O1 G; c& I  r, C& a) B$ y
  42.     *__SIMD32(pDst)++ = __QADD16(inA1, inB1);
    ; J& {/ R. z4 n8 ]
  43.     *__SIMD32(pDst)++ = __QADD16(inA2, inB2);
    7 e- q$ V' S) z: e  g( J0 }
  44. 9 `: {% x* u) j8 b4 e6 V& r+ e) ~
  45.     /* Decrement the loop counter */
    4 f0 _9 N1 X* W* g- T) A9 v, I
  46.     blkCnt--;
    ' @6 d, _' n9 W& D: \
  47.   }
    7 x. D/ W! v0 `# u5 M/ q  P$ }& S

  48. & j) M, A  c  J7 W5 A" p8 O: a
  49.   /* If the blockSize is not a multiple of 4, compute any remaining output samples here.    # h7 g* o  }% z& A4 r+ ^' ^6 J/ ^# `
  50.    ** No loop unrolling is used. */
    2 F) ?! m! R0 A3 s& E2 y3 E
  51.   blkCnt = blockSize % 0x4u;
    & ~) v2 X. R1 {! b

  52. 5 J' q& `) e1 b; U" H4 e0 |
  53.   while(blkCnt > 0u)6 M$ m( ?  X. S* T3 _
  54.   {
    7 N+ D) {- U$ C; J
  55.     /* C = A + B */
    ; S4 N& l( ?6 P8 [
  56.     /* Add and then store the results in the destination buffer. */
    8 b; d' h' F# o" ]7 z4 W0 O2 f
  57.     *pDst++ = (q15_t) __QADD16(*pSrcA++, *pSrcB++);7 ]6 d) R7 U$ c* N: t+ e

  58. ( f/ ?4 q) a' I4 q! V+ s7 f
  59.     /* Decrement the loop counter */
    ( i! P( l+ R! e, D
  60.     blkCnt--;
    4 G' ^' ]8 a  e) O  }
  61.   }
    - Q' B, X$ W" ]: d* t$ W

  62. 6 M6 w9 r* u2 _" u; e, h
  63. #else) P# `) ~3 x- E6 P, Q. q6 H$ H
  64. % ^5 m6 {# i, h8 W6 m. b/ h; R
  65.   /* Run the below code for Cortex-M0 */9 v5 u+ ^* \! H7 v( z5 ]
  66. ! _/ U( U' @# Z9 Q

  67. 0 Y. H. T! b( s9 O& R

  68. - n/ [; X8 e  L0 V& x4 H
  69.   /* Initialize blkCnt with number of samples */
    & ~2 {( w$ U, m1 J
  70.   blkCnt = blockSize;8 H1 w8 J& Z+ F

  71. - T$ |0 f& }. d+ a! q
  72.   while(blkCnt > 0u)1 F8 b# k3 h5 [( l5 j% D
  73.   {
    9 `/ j4 {% r+ @8 j
  74.     /* C = A + B */6 U5 F) f7 M8 \: c
  75.     /* Add and then store the results in the destination buffer. */$ ~  [! G1 T' `2 O! S
  76.     *pDst++ = (q15_t) __SSAT(((q31_t) * pSrcA++ + *pSrcB++), 16);                                      (3)
    ' P8 g9 k) q& @* D

  77. 1 ?+ O2 j+ T  z) v
  78.     /* Decrement the loop counter */
    ' b% F. K9 G9 q
  79.     blkCnt--;% T- U+ D6 l! z9 ?: W% J
  80.   }) z( J1 ?. |. G

  81. + F- }( J2 p0 I  `7 E$ Q
  82. #endif /* #ifndef ARM_MATH_CM0_FAMILY */
      w3 O/ y- p: s/ Z
  83. % \  p; J* J) a

  84. ! s& X& T: e0 i7 ]) }( ~3 T
  85. }
复制代码
1. 这个函数也是饱和运算,输出结果的范围[0x8000 0x7FFF],超出这个结果将产生饱和结果。
2. 函数inA1 = *__SIMD32(pSrcA)++仅需要一条SIMD指令即可完成将两个16位数存到32位的变量inA1中。
3. __SSAT也是SIMD指令,这里是将结果饱和到16位精度。
8.2.4 arm_add_q7
    这个函数用于求8位定点数的绝对值,源代码分析如下:
  1. /**   
    0 ~: M) L- {5 c5 I4 P; Z. J
  2. * @brief Q7 vector addition.    # Q3 W9 J2 d, [* p% b; g+ Y
  3. * @param[in]       *pSrcA points to the first input vector   
    1 a6 T. m5 R5 Q, c, }
  4. * @param[in]       *pSrcB points to the second input vector   
    5 Y1 B' r6 r, ~0 R2 ^
  5. * @param[out]      *pDst points to the output vector   
    ) h" m9 w6 L" `; }& s$ m
  6. * @param[in]       blockSize number of samples in each vector   
    : o) F& P0 B. A
  7. * @return none.   
    * t' L5 k9 ]6 q+ e+ I, n0 g) `
  8. *    9 U: Q$ [# \3 l- `; F$ v& }+ Q
  9. * <b>Scaling and Overflow Behavior:</b>                                                              (1)6 w/ c6 Z2 ~6 g' L9 b5 I0 ?2 |& b
  10. * \par   
    % o" A0 u6 h( \
  11. * The function uses saturating arithmetic.    " N( [! S, A# }* Z. ~
  12. * Results outside of the allowable Q7 range [0x80 0x7F] will be saturated.    5 E2 x4 x* B9 V; V5 X8 l5 A' d
  13. */: |6 p$ c) K$ q5 T' r7 `

  14. 2 u  e5 x& m8 S# r0 C/ F
  15. void arm_add_q7(
    6 {' k5 B  @' G% F6 }7 Z- |
  16.   q7_t * pSrcA,
    : V8 `  q% ~; {
  17.   q7_t * pSrcB,! W4 x1 \6 `/ d5 ]
  18.   q7_t * pDst,0 x* E* g' z- w2 x$ M7 O; u
  19.   uint32_t blockSize)
    * L  e4 M) r3 j0 W
  20. {! _+ g% r: W- u8 w4 f6 R
  21.   uint32_t blkCnt;                               /* loop counter */( C& Z( D0 I2 L$ W& z5 z' v

  22. ' W2 {; M) E0 V3 Q# I
  23. #ifndef ARM_MATH_CM0_FAMILY) G( Z6 r0 N, M! ^  P( {  N

  24. : M8 {# S, U$ m' K& @+ ?
  25. /* Run the below code for Cortex-M4 and Cortex-M3 */
    # R5 `) i, @& v& p4 t% I
  26. . N% V+ \$ q6 O, \- n
  27. 8 w7 C0 A) N$ z' F  m$ [
  28.   /*loop Unrolling */0 o4 s) w9 @: I& H6 W
  29.   blkCnt = blockSize >> 2u;
    & s* W$ J+ G, [% n& }

  30. 2 H% @8 ^& G' |0 y7 M1 V, X
  31.   /* First part of the processing with loop unrolling.  Compute 4 outputs at a time.   
    ) {4 R6 U; |/ ~  a/ J- X' Z1 n
  32.    ** a second loop below computes the remaining 1 to 3 samples. */: d) \6 a, k# d8 o
  33.   while(blkCnt > 0u); y! r& {1 x3 {5 ~3 [
  34.   {
    7 a/ x/ O# u! j9 A% e
  35.     /* C = A + B */( J* F9 F7 R# d  X  u$ C  X4 t
  36.     /* Add and then store the results in the destination buffer. */                                 (2)7 H$ F( X9 e8 M0 r7 G7 q. h0 ^
  37.     *__SIMD32(pDst)++ = __QADD8(*__SIMD32(pSrcA)++, *__SIMD32(pSrcB)++);
    5 v, @- e, J+ n7 G
  38. 8 T0 x0 W$ ~; X5 d6 Y/ F
  39.     /* Decrement the loop counter */
    6 j% p/ I* N" r! L4 J
  40.     blkCnt--;
    * V8 H/ r; N' D6 ^
  41.   }4 i9 o0 |; q4 n3 k
  42. 4 E. F& h7 p" z
  43.   /* If the blockSize is not a multiple of 4, compute any remaining output samples here.   
    $ k) u& ]1 M& z: l- `
  44.    ** No loop unrolling is used. */+ h. z  n2 ~" T8 N0 h
  45.   blkCnt = blockSize % 0x4u;& G/ P5 e( t- Y6 t5 S2 [

  46. 0 H2 `. e; u/ m, h  d3 s
  47.   while(blkCnt > 0u), J: S& ~" d- C2 Q9 j5 j/ ?
  48.   {
    $ h0 k8 _% R% J7 A: s0 @, h: ~; p
  49.     /* C = A + B */
    2 J6 ]( L4 `# V$ C+ E% p
  50.     /* Add and then store the results in the destination buffer. */
    # X7 S& g8 j$ ~" X$ z- t# W1 _
  51.     *pDst++ = (q7_t) __SSAT(*pSrcA++ + *pSrcB++, 8);6 b7 N6 l! w& H; ]
  52. & J6 K* K; L- B# S
  53.     /* Decrement the loop counter *// Y6 d0 A  t- G
  54.     blkCnt--;
    + t& Y/ X' u. R$ Q5 K$ f3 a
  55.   }% k% n* ?4 v$ }/ F2 q
  56. . c1 n) s! a. k  `
  57. #else
    . g( D( \8 l4 G
  58. " w$ D3 F0 c7 U
  59.   /* Run the below code for Cortex-M0 */# |8 y& U3 l& Y5 h

  60. ' r+ ?0 C% a' Z' ~  n% N6 s* n

  61. * c' U6 u' p8 ?9 [  S

  62. # k: G! Q$ [( B8 ^; v5 \2 W
  63.   /* Initialize blkCnt with number of samples */5 H. q9 ], ?* I% k' z# x
  64.   blkCnt = blockSize;: d& I! f5 a/ U. D
  65. / p* u) D5 I: Z- B
  66.   while(blkCnt > 0u)
      v7 m3 p; Z' @2 a1 W0 `1 q$ y/ s1 u& v
  67.   {
    & X# S  D2 |, {4 C$ o
  68.     /* C = A + B */" r, Z; P7 P6 W+ S
  69.     /* Add and then store the results in the destination buffer. */6 I: n0 L/ l8 s0 a& o
  70.     *pDst++ = (q7_t) __SSAT((q15_t) * pSrcA++ + *pSrcB++, 8);4 f( D& v7 n2 t, ]& ]. `

  71. 6 i% d, K0 ^/ Q
  72.     /* Decrement the loop counter */+ o1 v5 E$ h$ O& L9 \; v! j
  73.     blkCnt--;
    & F2 o" T& P/ B- N' i  Q. }
  74.   }
    4 G# M6 H2 v- O+ h- U

  75. 9 f8 b/ w7 [- Q: i) U$ V
  76. #endif /* #ifndef ARM_MATH_CM0_FAMILY */
    0 o$ L9 g# A! o. @! X. Z  Q$ p6 n

  77. / A& Z; h+ I2 h
  78. 3 w3 u3 Q5 m, H6 Z" u
  79. }
复制代码
1. 这个函数也是饱和运算,输出结果的范围[0x80 0x7F],超出这个结果将产生饱和。
2. 这里通过SIMD指令实现4组8位数的加法。
8.2.5 实例讲解
实验目的:
    1. 四种类似数据的求和
实验内容:
    1. 按下按键K2, 串口打印输出结果
实验现象:
    通过窗口上位机软件SecureCRT(V5光盘里面有此软件)查看打印信息现象如下:
8.2.png
程序设计:
  1. /*
    0 w) K. s- M. e: h
  2. *********************************************************************************************************
    - ?9 O8 p  U: F& Q
  3. *        函 数 名: DSP_ABS' ^2 r. ^5 x7 G: @$ c! j
  4. *        功能说明: 加法+ k7 ^% G. C/ q
  5. *        形    参:无& J5 ]9 R1 P- Z- c+ I- \
  6. *        返 回 值: 无
    ! S7 w- \0 I5 d9 T$ B
  7. *********************************************************************************************************
    # W! T1 ~: C& U6 ^
  8. */) c/ e% _/ u4 J* f9 Q
  9. static void DSP_Add(void)8 \  K& H# e3 C% i9 H4 _
  10. {3 b# G1 J" P; v, X) F
  11. static float32_t   pSrcA;1 ~: e0 Y. C/ j( m5 I0 O
  12. static float32_t   pSrcB;  
    5 L8 b: X/ n3 f% {% a3 w  G$ ~
  13. static float32_t   pDst;  1 H* A: r: G+ N8 J
  14. static q31_t  pSrcA1;  & g8 }" ?; x  e: d) V
  15. static q31_t  pSrcB1;  2 Q7 b8 L) _8 l# k) _
  16. static q31_t  pDst1;  
    8 O0 p: m2 U; y. m4 ~& a

  17. ' T4 [# h% p9 c
  18. static q15_t  pSrcA2;  
    : ~" g. J" M* [2 t/ p4 O
  19. static q15_t  pSrcB2;  6 |) f, W5 n. j  o! \
  20. static q15_t  pDst2; 5 ^- a& }3 _2 z7 w% m2 x; X& t. G: H4 G
  21. + _, @) a7 Q9 Z# J5 Y* r
  22. static q7_t  pSrcA3; ( g. x. S1 s& V
  23. static q7_t  pSrcB3;  ' b0 j9 l5 v) o' A" q: n
  24. static q7_t  pDst3;  3 m/ c3 ^% e: i9 x2 |: z
  25. 2 k" c$ z; U( l+ h
  26. pSrcA--;
      p) D. u% h  K9 Y1 p# e
  27. arm_add_f32(&pSrcA, &pSrcB, &pDst, 1);
    , J) V( x: S) j
  28. printf("arm_add_f32 = %f\r\n", pDst);% u$ |4 G* y* p! H

  29. % O" o3 B" D! p4 X
  30. pSrcA1--;& S$ h+ r2 j' }9 f4 s
  31. arm_add_q31(&pSrcA1, &pSrcB1, &pDst1, 1);
    $ j( c! j* W6 ]9 d& h% _
  32. printf("arm_add_q31 = %d\r\n", pDst1);# p; u5 }; q% x! @& b6 \4 }% P

  33. . @; n+ k; c% a
  34. pSrcA2--;
    ) L$ k; |, a# P
  35. arm_add_q15(&pSrcA2, &pSrcB2, &pDst2, 1);4 L, N% [& c" x# A* k
  36. printf("arm_add_q15 = %d\r\n", pDst2);+ M0 e8 l5 k: t$ R* o
  37. ( G6 }- i" e6 {2 }2 E' |2 u' F
  38. pSrcA3--;: F+ W$ l% P; I6 g
  39. arm_add_q7(&pSrcA3, &pSrcB3, &pDst3, 1);: ?% E- P* X3 p+ s
  40. printf("arm_add_q7 = %d\r\n", pDst3);0 W# D- n5 Y8 O) v8 n/ |1 b
  41. printf("***********************************\r\n");- h  A% I9 C  |- C4 u7 t
  42. }
复制代码

5 }1 }3 ~7 G" p* y; O' v
baiyongbin2009 回答时间:2015-3-18 11:45:34
8.4 乘法(Vector Multiplication)
    这部分函数主要用于乘法,公式描述如下:
     pDst[n] = pSrcA[n] * pSrcB[n],   0 <= n < blockSize.   
8.4.1 arm_mult_f32
     这个函数用于求32位浮点数的乘法,源代码分析如下:
  1. /**        * Y, Y0 Q( `4 i2 }- _
  2. * @brief Floating-point vector multiplication.        9 p0 L& s! u3 D. h& |! w+ \) q
  3. * @param[in]       *pSrcA points to the first input vector        + e' I8 ]* L: x4 \% _
  4. * @param[in]       *pSrcB points to the second input vector        8 y  m, K$ D0 H' u
  5. * @param[out]      *pDst points to the output vector        
    / B/ M- E' b7 Y6 k$ E# y
  6. * @param[in]       blockSize number of samples in each vector        
    ) K' z3 `& Q4 T3 g
  7. * @return none.        1 X  ]! g; q1 h# F
  8. */
    , d; p/ l' P" e+ m) I

  9. ; a. @# t& E4 T  B7 r  V
  10. void arm_mult_f32(* ]! e3 q2 J4 x5 `& s" d. c
  11.   float32_t * pSrcA,
    ( ?& q) O9 ]2 c9 R: ~
  12.   float32_t * pSrcB,
    ( U+ {! i4 e6 i! z3 r
  13.   float32_t * pDst,/ C& y" O$ m" O& d
  14.   uint32_t blockSize)- G( E' A5 f9 H2 j+ o$ K6 N6 ~9 S- u, l
  15. {& G. c0 w  T: w) ~& L; q
  16.   uint32_t blkCnt;                               /* loop counters */+ o, e9 b& x9 p0 i$ l1 o3 W
  17. #ifndef ARM_MATH_CM0_FAMILY* g) ~( e' H% j: {/ p; C0 S
  18.   h7 _% X3 U- S: ]0 I. \  c
  19.   /* Run the below code for Cortex-M4 and Cortex-M3 */
    0 Y# X% l) y3 O
  20.   float32_t inA1, inA2, inA3, inA4;              /* temporary input variables */
    9 C; @$ O2 q) J% X( M. ^3 }
  21.   float32_t inB1, inB2, inB3, inB4;              /* temporary input variables */) C9 ~7 m9 c/ i) [
  22.   float32_t out1, out2, out3, out4;              /* temporary output variables */
    " E6 S; ~  G1 U- }+ W
  23. & ~; L6 G. L" n' U
  24.   /* loop Unrolling */
    * i+ Q! F' h9 a
  25.   blkCnt = blockSize >> 2u;
    0 P0 W1 B) t# L) A; l( |, p

  26. . ^! B1 t3 `9 |$ k& q
  27.   /* First part of the processing with loop unrolling.  Compute 4 outputs at a time.        
    ; n7 g/ `+ n& d( s
  28.    ** a second loop below computes the remaining 1 to 3 samples. */
    0 h5 J, G7 ^8 Q1 X1 k1 R/ N0 D
  29.   while(blkCnt > 0u)7 G8 X: ?9 w5 n% N" u/ i, s/ s
  30.   {
    ( E! Z9 S8 |* \+ ]- _
  31.     /* C = A * B */0 |7 u" u; o" N( |0 A3 V
  32.     /* Multiply the inputs and store the results in output buffer */                                 (1)
    ) y9 U9 P% o; F0 z
  33.     /* read sample from sourceA */5 U6 S, i2 ^4 z. d" U
  34.     inA1 = *pSrcA;
    6 k8 a. X8 r  w  m! k" L
  35.     /* read sample from sourceB */" o, s# L  s( m7 i4 T+ O  U' ^1 I
  36.     inB1 = *pSrcB;
    % ^* `& Y3 O9 }3 C. }, l4 l+ j, l) Z
  37.     /* read sample from sourceA */! S1 N. U( \' d( @3 m. I1 L7 X
  38.     inA2 = *(pSrcA + 1);2 O0 e# o; Q3 v( f8 T9 q
  39.     /* read sample from sourceB */, @. V! w, o1 v! r; D( y7 u+ V
  40.     inB2 = *(pSrcB + 1);6 a3 M# P9 j$ f& C

  41. ) Y% ^- S9 l& L
  42.     /* out = sourceA * sourceB */! N' E. E% S; |5 ]. K2 [
  43.     out1 = inA1 * inB1;
      @* m. Z/ J7 o2 M

  44. 4 R$ n& y" c$ n  G+ P
  45.     /* read sample from sourceA */  U  g( R" X; X" E
  46.     inA3 = *(pSrcA + 2);) R, |9 x' V6 v% H& z8 x7 `
  47.     /* read sample from sourceB */1 L+ n! X5 ]1 o2 I# P
  48.     inB3 = *(pSrcB + 2);. I( j! r4 ]# c% i, p

  49. / e3 e7 N; }  f) F; P# c
  50.     /* out = sourceA * sourceB */8 m) C3 ~7 L/ P: `1 z$ r
  51.     out2 = inA2 * inB2;2 Y6 A* @- _% a9 i

  52. / l. ~1 U+ M+ l& m) F: G
  53.     /* read sample from sourceA */
    . c# Q! B5 D. K3 x
  54.     inA4 = *(pSrcA + 3);
    7 k/ u2 C9 ~2 _, {* Y! I0 |$ n

  55. 4 `( N# f% {5 G6 G# |% b0 Q
  56.     /* store result to destination buffer */
    $ N% V4 p/ {; Z- U  D6 f
  57.     *pDst = out1;7 o6 f9 }6 X/ b+ J! B7 b

  58. 4 S2 J0 b6 g6 T$ L& c: [- }- V
  59.     /* read sample from sourceB */7 ^8 D8 K! ]) f! k! g3 t" m
  60.     inB4 = *(pSrcB + 3);9 R( ?, u/ i0 e; e  l

  61. + _; I. K- M& S' t/ ?7 i/ _  o  N
  62.     /* out = sourceA * sourceB */' d; {( S3 }* x8 I, i+ [9 }. }  J
  63.     out3 = inA3 * inB3;
    / \- F) R# o( r9 ?4 J) d8 k- F
  64. 8 d" m% n# c$ \9 v" h
  65.     /* store result to destination buffer */
    $ l& B0 v% ]% g5 Z
  66.     *(pDst + 1) = out2;; t! t) [$ M: b9 p

  67. + m. [8 F6 G. H5 H9 K
  68.     /* out = sourceA * sourceB */% S$ ^% L0 \' J! ~; |0 F# r5 V
  69.     out4 = inA4 * inB4;( K, A2 t' r# `, U. U& T
  70.     /* store result to destination buffer */! b1 G8 Y' Z  L0 ]: u7 n+ O% j
  71.     *(pDst + 2) = out3;
    6 y- l1 `& X3 V
  72.     /* store result to destination buffer */
    1 _1 j; m+ _5 ?- {2 E5 h9 n7 K
  73.     *(pDst + 3) = out4;. m, s+ f& w! m8 E

  74. ; d7 w1 p# x- r& X7 v

  75. $ V9 T  o) l, f8 h' M: K% p' D2 S
  76.     /* update pointers to process next samples */
    ; m9 Z, d( P8 n5 Z" w3 S6 w
  77.     pSrcA += 4u;
    8 s. @7 |2 l$ v4 V& q, K
  78.     pSrcB += 4u;* i1 b; E) |! s0 H9 l$ q
  79.     pDst += 4u;
    2 N5 I0 b& R9 \5 j( ?2 V& m$ w

  80. , V( h7 v5 i, J
  81.     /* Decrement the blockSize loop counter */2 N8 L7 y7 ?0 B% ]8 W# m
  82.     blkCnt--;6 ^8 \* E1 L( C" Z. ~0 m# R: D( m
  83.   }
    / L# F3 N  M3 X, N0 N- t% s

  84. , M4 U/ J6 f9 k9 q
  85.   /* If the blockSize is not a multiple of 4, compute any remaining output samples here.        ) p. P# h* g# e
  86.    ** No loop unrolling is used. */
    1 x) A: i, R8 T! y- D5 }0 `" F
  87.   blkCnt = blockSize % 0x4u;
    8 y7 h4 j- e! m( X! h
  88. 1 l# |# j8 m3 M+ G$ w- |
  89. #else) ?) A. r9 T! f- c) {3 a! `

  90. 0 {2 r; ?. V5 u3 R8 A9 c& O
  91.   /* Run the below code for Cortex-M0 */
    * b: Y) N9 L0 G

  92. ( u# b. Y3 @8 t$ ^
  93.   /* Initialize blkCnt with number of samples */  }+ b: `1 A: a
  94.   blkCnt = blockSize;
    * [  ?% a. W  x, T( d" T6 ?

  95. ; {6 g- z: _, V
  96. #endif /* #ifndef ARM_MATH_CM0_FAMILY */5 ^5 ?+ s0 }) J9 E2 m
  97. ) e, \# `) ]5 y( ]# }% X  j
  98.   while(blkCnt > 0u)% R! j- x- {: C  I
  99.   {( B6 P2 ^1 I/ |
  100.     /* C = A * B */
    1 a6 O& k* g; R# m; H% v9 h3 Z" B8 a
  101.     /* Multiply the inputs and store the results in output buffer */$ J+ x9 I. ?5 D2 W1 u/ P8 j
  102.     *pDst++ = (*pSrcA++) * (*pSrcB++);( B# m! T5 v; s) F3 ^. {

  103. & Q  F) ?- ^3 }- |: u9 J$ [
  104.     /* Decrement the blockSize loop counter */- B' U3 m- ~# ?% y. X4 u' P! R
  105.     blkCnt--;4 k( x9 Y; j$ d' R% y8 l
  106.   }
    2 Y+ l' Z: K, y5 J
  107. }
复制代码
1. 浮点的32位乘法比较简单,这里依然是以4次的计算为一组。
8.4.2 arm_mult_q31
    这个函数用于求32位定点数的乘法,源代码分析如下:
  1. /**   
    3 o  y9 a3 T0 J& p/ I6 T
  2. * @brief Q31 vector multiplication.   
    ! J. }0 W- Y8 h0 ]
  3. * @param[in]       *pSrcA points to the first input vector   
    3 a8 D2 I. A) A$ q- Z
  4. * @param[in]       *pSrcB points to the second input vector   
    5 p6 G, r+ ~! w) u7 {2 U
  5. * @param[out]      *pDst points to the output vector   
    : ]/ e- o# S: M. `
  6. * @param[in]       blockSize number of samples in each vector   
    # M6 B& L5 c  e0 |; y4 H9 o
  7. * @return none.    - t* y. m& ]+ }8 r: L
  8. *    / S8 z4 ]7 ]; A
  9. * <b>Scaling and Overflow Behavior:</b>                                                             (1)$ O4 x7 S  _  n3 L( u
  10. * \par   
    7 z# R' I# d. Q
  11. * The function uses saturating arithmetic.   
    ( x9 B4 ~0 L& h- }2 L+ f3 g+ a
  12. * Results outside of the allowable Q31 range[0x80000000 0x7FFFFFFF] will be saturated.    " o/ t5 i5 G$ s2 A0 l
  13. */
    ( O' Z& G6 y) i6 r

  14. . o6 a/ a( O( U$ b
  15. void arm_mult_q31(7 r  A. y9 p) _9 [* G
  16.   q31_t * pSrcA,' Y$ V3 j4 V$ |
  17.   q31_t * pSrcB,
    3 z2 n0 j2 F$ M* ~- E5 @, K
  18.   q31_t * pDst,7 a0 q  m# l: h0 d. V
  19.   uint32_t blockSize)7 m* R6 ~1 r- P! P0 H
  20. {
    : \6 P4 Y% J4 \1 h& d9 ?
  21.   uint32_t blkCnt;                               /* loop counters */$ p% S1 y5 w/ @* k  R( J# `' \  J

  22.   h4 t$ {$ o1 w: P7 e% N
  23. #ifndef ARM_MATH_CM0_FAMILY% @* F0 t7 W0 b6 R6 X7 M

  24. ! q* x0 E* o) v4 k" G% n& Z
  25. /* Run the below code for Cortex-M4 and Cortex-M3 */
    " @& w2 |" }' h/ Z6 q
  26.   q31_t inA1, inA2, inA3, inA4;                  /* temporary input variables */
    , |- M0 j# w5 y/ a) d* x9 n. y+ m
  27.   q31_t inB1, inB2, inB3, inB4;                  /* temporary input variables */
    6 I9 @3 Q2 m" O$ g! a( g
  28.   q31_t out1, out2, out3, out4;                  /* temporary output variables */
    " p0 n+ O- B/ l* Z( Y6 s. V
  29. 3 C8 W% h  c9 f' J; [8 l6 I
  30.   /* loop Unrolling */5 q5 \0 f$ }4 S
  31.   blkCnt = blockSize >> 2u;
    - [. e9 U% l- @  f0 b, d2 k
  32. 9 R7 C5 ~$ \9 w8 X3 s
  33.   /* First part of the processing with loop unrolling.  Compute 4 outputs at a time.    . s/ O5 t' L0 C* q- d8 Y: y: D5 O
  34.    ** a second loop below computes the remaining 1 to 3 samples. */
    $ W4 {7 V' o% s2 }% Z2 S5 ~
  35.   while(blkCnt > 0u)
    ' M8 B  [- G* h: C2 {
  36.   {! }: {+ Q6 ?* S& w1 K2 m
  37.     /* C = A * B */4 A5 {2 \8 E. F6 j
  38.     /* Multiply the inputs and then store the results in the destination buffer. */5 m% e4 K0 @( B6 w: M2 k; j
  39.     inA1 = *pSrcA++;+ N5 H: B, ]2 k# D* b
  40.     inA2 = *pSrcA++;) v. l; V* K' A. ]! S
  41.     inA3 = *pSrcA++;# q' j0 ?2 k; `+ }# }. C( u  ~
  42.     inA4 = *pSrcA++;/ f9 C  L) ^" h& w  V
  43.     inB1 = *pSrcB++;4 G' y8 W3 p. X6 K9 p7 i
  44.     inB2 = *pSrcB++;
    5 T+ o7 o. i. r+ T* T
  45.     inB3 = *pSrcB++;
    : J8 \3 ?+ X( ], u0 ~
  46.     inB4 = *pSrcB++;
    - A0 O5 P; T& t5 a

  47. # X, q1 f  ~% S8 b* w5 x
  48.     out1 = ((q63_t) inA1 * inB1) >> 32;                                                              (2)
    $ d, Y* w; Y9 v* M  m
  49.     out2 = ((q63_t) inA2 * inB2) >> 32;
    ! E+ h$ r1 c* L, p3 k3 O7 J9 o6 i
  50.     out3 = ((q63_t) inA3 * inB3) >> 32;. J  u* i. ^+ k
  51.     out4 = ((q63_t) inA4 * inB4) >> 32;7 J0 b! q, ?/ J/ o: C; d' ]+ }3 K/ b
  52. 4 \% O: i  Y0 f' W% H+ O
  53.     out1 = __SSAT(out1, 31);                                                                         (3)
    ! y: S5 |) f: W% |
  54.     out2 = __SSAT(out2, 31);/ l+ _# e, p0 ]; y4 q; [
  55.     out3 = __SSAT(out3, 31);
    2 D5 C8 N+ {! W8 d3 }3 v$ j% A
  56.     out4 = __SSAT(out4, 31);
    # C% D9 H9 }# B# p& X* h$ z$ F0 B, N
  57. 0 e6 x7 C9 a: r8 w( U
  58.     *pDst++ = out1 << 1u;                                                                            (4)
    + _2 h6 O. `0 p+ P
  59.     *pDst++ = out2 << 1u;9 n4 x: d2 u5 P* p: _
  60.     *pDst++ = out3 << 1u;) X; g: w$ t$ c5 V2 d  T7 ]' E
  61.     *pDst++ = out4 << 1u;
    5 e& c; q. ]' ?  e, Y: {( o, O

  62. # \1 B6 `# C" T+ e
  63.     /* Decrement the blockSize loop counter */' R' [4 o% i( k9 W& k* Y. d5 b: [
  64.     blkCnt--;, s) k# ~0 J, g
  65.   }" \1 {$ ~8 G( c. C# V) I2 X
  66. & m: g6 ^% T- e( ^) \" G2 T
  67.   /* If the blockSize is not a multiple of 4, compute any remaining output samples here.   
    5 ]$ C$ Z1 o( U/ P6 T9 H
  68.    ** No loop unrolling is used. */
    / F+ ?/ k. [# x, F
  69.   blkCnt = blockSize % 0x4u;
    6 C7 E8 s2 H+ P- x, ]* E

  70. ( q+ J2 W& T: P
  71. #else
    2 _* d# G3 |2 W5 p5 w. b+ p

  72. : N! V" P' I0 q1 W
  73.   /* Run the below code for Cortex-M0 */" y4 R+ ?0 x2 Q
  74. ) B) ~/ g" b3 Q) D
  75.   /* Initialize blkCnt with number of samples */8 t1 R5 U$ G" P# L3 m
  76.   blkCnt = blockSize;
    ) u) d- I! F8 [' D3 M
  77. % T/ D# H1 I8 W$ R+ Y; J
  78. #endif /* #ifndef ARM_MATH_CM0_FAMILY */: U, f: ]& G6 e

  79. ' l! q+ v3 W$ C8 d
  80.   while(blkCnt > 0u)! W+ b- x! R, O3 K- H" Y
  81.   {6 J% w$ J1 r6 P
  82.     /* C = A * B */7 K/ H' l" W0 P6 |9 t+ ~3 W: k2 T
  83.     /* Multiply the inputs and then store the results in the destination buffer. */6 ?, S: {  R+ n: J
  84.     *pDst++ =
    , j; I% L4 v( e5 F
  85.       (q31_t) clip_q63_to_q31(((q63_t) (*pSrcA++) * (*pSrcB++)) >> 31);
    7 ]$ c( h* u4 c: x5 z% f

  86. ' n' \* Z% v& t& [' w  ]' G
  87.     /* Decrement the blockSize loop counter */
    5 w2 }9 y* g- v6 E# s- y
  88.     blkCnt--;; d  P$ ]2 w( H0 c7 P9 P0 ]
  89.   }# K  a6 F) M4 k8 p6 h& |
  90. }
复制代码
1. 这个函数使用了饱和算法。
     所得结果是Q31格式,范围Q31 range[0x80000000 0x7FFFFFFF]。
2. 所得乘积左移32位。
3. 实现31位精度的饱和运算。
4. 右移一位,保证所得结果是Q31格式。
8.4.3 arm_mult_q15
    这个函数用于求16位定点数的乘法,源代码分析如下:
  1. /**   
    / W4 l: Y7 |2 l: k7 Q; F: ?8 S
  2. * @brief           Q15 vector multiplication    8 B! Z8 f9 B2 ?
  3. * @param[in]       *pSrcA points to the first input vector    ' F2 Q5 |# S3 y
  4. * @param[in]       *pSrcB points to the second input vector    / ]* A' j( M( R& O5 W
  5. * @param[out]      *pDst points to the output vector   
      f& b% P6 X1 e3 f# v) b0 @
  6. * @param[in]       blockSize number of samples in each vector    ' g& w9 ?# p9 M+ N
  7. * @return none.   
    : p8 p1 Y3 ~% [4 C/ B6 Y
  8. *    . d) q! z6 [8 O% ?- c% h& q" K
  9. * <b>Scaling and Overflow Behavior:</b>                                                              (1)
    , n0 S. Y0 W7 Z0 R/ q; E, A$ R2 e
  10. * \par      y9 w6 K! H0 T0 V8 z8 [
  11. * The function uses saturating arithmetic.    ' A; m9 q( @; ]$ q
  12. * Results outside of the allowable Q15 range [0x8000 0x7FFF] will be saturated.   
    2 z6 w" h/ i1 B' V8 N6 f7 C+ B% L
  13. */4 |7 @( L, f" ]. i. A4 z. A

  14. ! O4 P' c2 L3 l" h) x( ~8 q
  15. void arm_mult_q15(
    + x' K' W( @  ?! U% o' @8 @) ^% ~% L
  16.   q15_t * pSrcA,
    5 K' Y. v3 n/ _
  17.   q15_t * pSrcB,( F* h9 c8 d) H! w2 ~
  18.   q15_t * pDst,$ N, B6 Q1 Q5 r( q) v, ]
  19.   uint32_t blockSize)
    % C" @4 B% F9 u3 D
  20. {
    9 o. d- Z( ]6 m) s" U. A
  21.   uint32_t blkCnt;                               /* loop counters */
    ; D8 h7 |" N+ E# I. {. m0 |

  22. # t  ]0 L9 j1 L* Y, {$ S- x
  23. #ifndef ARM_MATH_CM0_FAMILY
    7 u  E, x; A, R! B5 @9 X

  24. 1 X3 j1 z5 T' P- {, `
  25. /* Run the below code for Cortex-M4 and Cortex-M3 */8 e  U. f! u6 g; y& n7 S+ X4 A0 i
  26.   q31_t inA1, inA2, inB1, inB2;                  /* temporary input variables */6 |+ e, V( T, I% W+ o6 r' V* H
  27.   q15_t out1, out2, out3, out4;                  /* temporary output variables */
    ( |7 ^1 C* t' x' @! S
  28.   q31_t mul1, mul2, mul3, mul4;                  /* temporary variables */
    ( Z5 O" f9 d2 q; |; k
  29. ; X/ G3 J+ B  l
  30.   /* loop Unrolling */
    2 U3 g6 Z9 Y7 w) i2 `6 d
  31.   blkCnt = blockSize >> 2u;
    , }( A  a  u- o
  32. % f# D" v( m) _, f, B4 ^
  33.   /* First part of the processing with loop unrolling.  Compute 4 outputs at a time.        - D- i9 ^% b5 \9 }2 {2 \; q
  34.    ** a second loop below computes the remaining 1 to 3 samples. */) Z9 h* q$ M" w$ u' D
  35.   while(blkCnt > 0u)
    : ^' Y: e$ p1 ?1 }5 G8 Z
  36.   {$ w* d2 x, [# D! i+ E+ g
  37.     /* read two samples at a time from sourceA */
    - Y7 M: T3 b; G+ e3 W0 D' z# P
  38.     inA1 = *__SIMD32(pSrcA)++;                                                                     (2)1 e+ [7 q+ C9 `3 @. ]4 L8 @
  39.     /* read two samples at a time from sourceB */) S/ U- m% D; M' C, ^4 Y
  40.     inB1 = *__SIMD32(pSrcB)++;
    7 }0 R; ]' j# }9 E/ b3 f% [
  41.     /* read two samples at a time from sourceA */
    & ~# u  {, B: S) a
  42.     inA2 = *__SIMD32(pSrcA)++;6 r5 T4 s0 R& u) n$ ]( Y" ?
  43.     /* read two samples at a time from sourceB */8 l. i" D2 t& @9 |8 d4 |$ E- Q" A
  44.     inB2 = *__SIMD32(pSrcB)++;0 O$ i/ D8 K: c7 \7 l4 K4 Q1 q
  45. 0 W/ B( X& N! l5 p8 C
  46.     /* multiply mul = sourceA * sourceB */
    * ?/ z' i2 j# n% }8 N
  47.     mul1 = (q31_t) ((q15_t) (inA1 >> 16) * (q15_t) (inB1 >> 16));                                  (3)
    # ?4 I  j9 C- y: p" s: G8 T
  48.     mul2 = (q31_t) ((q15_t) inA1 * (q15_t) inB1);1 F% |0 k' t' |5 ]: T0 N
  49.     mul3 = (q31_t) ((q15_t) (inA2 >> 16) * (q15_t) (inB2 >> 16));$ _* W" J  l+ J% A+ h( p4 f, f
  50.     mul4 = (q31_t) ((q15_t) inA2 * (q15_t) inB2);
    4 S# [* @" Y9 o9 n
  51. & B9 f1 q# n0 Y3 O( V
  52.     /* saturate result to 16 bit */8 p! x# r* g4 W; P; G, c+ h, h) ]
  53.     out1 = (q15_t) __SSAT(mul1 >> 15, 16);                                                         (4)
    3 |! C; P" q: w+ M
  54.     out2 = (q15_t) __SSAT(mul2 >> 15, 16);8 N) V$ e3 g. X5 h" c! D
  55.     out3 = (q15_t) __SSAT(mul3 >> 15, 16);/ C) p  Y4 e( o% Q- `/ d
  56.     out4 = (q15_t) __SSAT(mul4 >> 15, 16);
    ' D  t6 X, Z8 ~

  57. , V/ t- z" C7 F5 @* C5 o5 D
  58.     /* store the result */# Q! b$ ]7 V* j
  59. #ifndef ARM_MATH_BIG_ENDIAN9 n0 y  f6 h: z$ N5 n0 e6 j
  60. & v6 p2 A- }' r  p6 ^( D2 {% e
  61.     *__SIMD32(pDst)++ = __PKHBT(out2, out1, 16);                                                   (5)
    0 i" J$ V: C. t
  62.     *__SIMD32(pDst)++ = __PKHBT(out4, out3, 16);7 G; z8 r; Y( G" z
  63. ) M9 Z6 u) v. a' x% u3 R3 j
  64. #else1 \! _4 F6 W" a  G! \5 |9 [4 e
  65. 0 Y8 d% y7 p. z7 C
  66.     *__SIMD32(pDst)++ = __PKHBT(out2, out1, 16);4 Z$ B5 I* M" {9 d
  67.     *__SIMD32(pDst)++ = __PKHBT(out4, out3, 16);/ i% U/ W7 n! C7 B3 [6 U5 A. y- I
  68. 2 y+ @  K5 z' T! {! ^9 `
  69. #endif //      #ifndef ARM_MATH_BIG_ENDIAN
    3 P& d* L; Y- ~
  70. & |" @7 h3 q! C; m9 l
  71.     /* Decrement the blockSize loop counter */
    " a. w0 t6 d+ M+ w  g5 P
  72.     blkCnt--;: ^- N) g+ W. b
  73.   }% i, D! T( g/ X' q. n: Q! I) ^6 J
  74. 1 w, j7 U7 c; M( ~/ o* `2 @
  75.   /* If the blockSize is not a multiple of 4, compute any remaining output samples here.    ) m& O2 u9 c4 ]4 R
  76.    ** No loop unrolling is used. */
    % D  F  M/ m6 H# C, `0 o
  77.   blkCnt = blockSize % 0x4u;
    0 K) H3 O7 R4 J( S/ ]
  78. / V3 L5 Q2 |. _; a$ A
  79. #else
    . x+ p6 ^! B: T' V/ }4 s& h6 W
  80. % k7 M, X+ {/ E% P3 E( [; h
  81.   /* Run the below code for Cortex-M0 */9 L7 S. F( E3 F) ~- ^

  82. 1 q9 k& I4 f8 b/ i3 g
  83.   /* Initialize blkCnt with number of samples */
    ! r! K/ D( [3 J% ?7 b
  84.   blkCnt = blockSize;
    ) b, m$ u0 ~/ k  o/ x+ Y

  85. + P4 y% C+ [( @  k+ |4 z5 G  `4 ?
  86. #endif /* #ifndef ARM_MATH_CM0_FAMILY */& c3 L1 K% s# A/ N- n) Q/ e
  87. : u' S( {0 `2 _
  88. ) g, K5 X3 P3 q
  89.   while(blkCnt > 0u)8 Z/ w, `8 G3 L
  90.   {
    ; Q! `3 ]( n; b( q" b9 n4 v
  91.     /* C = A * B */6 y. Y* e4 Y" w' R: X( K
  92.     /* Multiply the inputs and store the result in the destination buffer */4 s! ?$ v9 F/ W$ Q" g# z
  93.     *pDst++ = (q15_t) __SSAT((((q31_t) (*pSrcA++) * (*pSrcB++)) >> 15), 16);8 Q: t' V5 i+ G7 i

  94. ( f1 B& Q9 J  m5 G
  95.     /* Decrement the blockSize loop counter */
    3 Z0 w/ N+ H( d8 @1 v
  96.     blkCnt--;2 E+ d9 \9 ~( Z& i& H. E- }" x- ~
  97.   }
    6 j( D: G; n% S! ^  q
  98. }
复制代码
1. 这个函数使用了饱和算法。
    所得结果是Q15格式,范围 [0x8000  0x7FFF]。
2. 一次读取两个Q15格式的数据。
3. 将四组数的乘积保存到Q31格式的变量mul1,mul2,mul3,mul4。
4. 丢弃32位数据的低15位,并把最终结果饱和到16位精度。
5. 通过SIMD指令__PKHBT将两个Q15格式的数据保存的结果数组中,从而一个指令周期就能完成两个数据的存储。
8.4.4 arm_mult_q7
    这个函数用于求8位定点数的乘法,源代码分析如下:
  1. /**    / K& d1 v1 b/ h  F2 v1 _
  2. * @brief           Q7 vector multiplication   
    $ I; q% X1 h; Q* ?
  3. * @param[in]       *pSrcA points to the first input vector    + ~$ j. }( ^: D1 E- u) t
  4. * @param[in]       *pSrcB points to the second input vector    6 J$ h! a+ R; F9 T9 U& v: S# x4 D
  5. * @param[out]      *pDst points to the output vector    3 F; y& I7 q* _7 h  r1 Q* n! }0 ~
  6. * @param[in]       blockSize number of samples in each vector   
    & r; W- R' y: p4 ^% _: K5 w8 f* M1 H% W
  7. * @return none.    . k& b+ ?8 h$ e
  8. *   
      J5 L, N! d- K' r7 M! a, q5 K* A
  9. * <b>Scaling and Overflow Behavior:</b>                                                             (1)
    1 P# r# Y& f3 g3 T! o
  10. * \par    0 b4 R0 k6 M' K
  11. * The function uses saturating arithmetic.      b8 C& M: Q% B! t# l3 E
  12. * Results outside of the allowable Q7 range [0x80 0x7F] will be saturated.   
    / _% S' e) x# X8 U  ?. H
  13. */
    9 }: \! a  y( w, s; R1 B

  14. 9 @! u( W" n6 X# A0 M
  15. void arm_mult_q7(& r3 E  r6 X( O5 F  d8 v2 ^; S' t
  16.   q7_t * pSrcA,7 @/ O! d) q# D$ ^
  17.   q7_t * pSrcB,
    ; N# C& c% q) Q; p$ ?
  18.   q7_t * pDst,
    $ _3 V7 z1 i: |" H
  19.   uint32_t blockSize)
    3 p  b9 t: K1 u/ o
  20. {
    6 X6 r4 R5 F: I/ ?
  21.   uint32_t blkCnt;                               /* loop counters */
    % c* @: g: [$ h% _5 p( x
  22. ' O, i; Q, p; {# }" N
  23. #ifndef ARM_MATH_CM0_FAMILY
    ) l( f0 D1 b9 Z5 I2 u/ Y7 C7 Z, G

  24. 4 d  c) d% M% U4 p# S
  25. /* Run the below code for Cortex-M4 and Cortex-M3 */( Z( \/ t, y6 T
  26.   q7_t out1, out2, out3, out4;                   /* Temporary variables to store the product */
    % ~6 O, F$ h8 w' F: W; J

  27. ( w2 M) }1 z1 f: o( c2 Z# `
  28.   /* loop Unrolling */
    ; H& e/ L7 D5 n9 f" K
  29.   blkCnt = blockSize >> 2u;2 A' I8 Y. n: x- x
  30. : t% ~7 ?7 v& |
  31.   /* First part of the processing with loop unrolling.  Compute 4 outputs at a time.    0 h) \) b! l, f& v' ]8 L
  32.    ** a second loop below computes the remaining 1 to 3 samples. */
    . q4 W! H2 u# [
  33.   while(blkCnt > 0u)* U$ s3 h0 D" k
  34.   {. k4 x$ _3 p. E' m4 h1 j
  35.     /* C = A * B */' A: w& R! V4 b  _! b1 t0 e
  36.     /* Multiply the inputs and store the results in temporary variables */                          (2)
    : x* H4 C9 O8 J  ?+ W! G/ J4 V! k
  37.     out1 = (q7_t) __SSAT((((q15_t) (*pSrcA++) * (*pSrcB++)) >> 7), 8);( A4 J8 C1 C0 `. A+ M. l
  38.     out2 = (q7_t) __SSAT((((q15_t) (*pSrcA++) * (*pSrcB++)) >> 7), 8);
    3 H6 [' M; B$ W4 `# d; J
  39.     out3 = (q7_t) __SSAT((((q15_t) (*pSrcA++) * (*pSrcB++)) >> 7), 8);# S+ q4 y# j* W" e
  40.     out4 = (q7_t) __SSAT((((q15_t) (*pSrcA++) * (*pSrcB++)) >> 7), 8);3 ^  g# S. f- t+ \) c7 @0 d
  41. 1 X$ u4 U7 e  W% d0 z
  42.     /* Store the results of 4 inputs in the destination buffer in single cycle by packing */
    / O3 v( ?$ T! j, s) H( }" J9 g
  43.     *__SIMD32(pDst)++ = __PACKq7(out1, out2, out3, out4);                                          (3)
    4 C) m* I' L4 p$ U

  44. 6 \5 x; b& r/ j0 u
  45.     /* Decrement the blockSize loop counter */, }' R/ }# j8 S
  46.     blkCnt--;
    8 q* u  d3 a: h  i+ q
  47.   }
    1 A& E! h, N$ S' c2 k, Q- }% g

  48. # L6 v( H5 _, @/ n/ Z% F6 B( N3 X5 p
  49.   /* If the blockSize is not a multiple of 4, compute any remaining output samples here.    7 X3 D6 l" G& M1 E, [4 H4 h1 @+ T
  50.    ** No loop unrolling is used. */
    ' |* g* j) b* Q3 w- \* B
  51.   blkCnt = blockSize % 0x4u;" K& q8 ^8 \; _  X2 h+ p
  52. / U9 P5 J3 G) Z+ H, o
  53. #else
    2 f  o3 A2 Q; r4 y! a  O

  54. * }- q% s2 C- L" H, h
  55.   /* Run the below code for Cortex-M0 */
    2 B+ M. k0 E* p4 L% u

  56. 6 K$ M6 l  K# t0 b+ G5 x
  57.   /* Initialize blkCnt with number of samples */
    / E6 Z" C0 Q9 v/ H6 e4 j
  58.   blkCnt = blockSize;( a3 o+ I& x! f+ c/ I* E3 b

  59. ( ~9 O; M0 f2 @% L' n* `0 I4 |6 `, D
  60. #endif /* #ifndef ARM_MATH_CM0_FAMILY */
    6 q& R7 t# `: l- A' W$ f' }

  61. 8 m- d2 X6 E2 J; A/ `  j5 B" Q
  62. ' C4 f& ~8 u8 i+ N1 w
  63.   while(blkCnt > 0u)- G& M  I1 k  `: u
  64.   {
    ; W& C# p. e2 ]" p0 I8 n, C- F
  65.     /* C = A * B */& @# {7 m' p4 |0 k% ?4 h# N+ a1 Q
  66.     /* Multiply the inputs and store the result in the destination buffer */+ N$ H! e9 {0 ]+ Z0 d5 \$ T
  67.     *pDst++ = (q7_t) __SSAT((((q15_t) (*pSrcA++) * (*pSrcB++)) >> 7), 8);3 m) h5 k/ t6 Z, U/ B% z3 l

  68. 9 f2 |  V+ [! c
  69.     /* Decrement the blockSize loop counter */2 `7 e7 x, p+ i/ Z! T- m$ |
  70.     blkCnt--;
    3 j7 D1 Q3 G$ V% K. T
  71.   }4 s  B. ~0 J+ x# x. ]" y4 F& Y" B* J% e
  72. }
复制代码
1. 这个函数使用了饱和算法。
    所得结果是Q7格式,范围 [0x80  0x7F]。
2. 将两个Q7格式的数据乘积左移7位,也就是丢掉低7位的数据,并将所得结果饱和到8位精度。
3. __PACKq7函数可以在一个时钟周期就能完成相应操作。
8.4.5 实例讲解
实验目的:
1. 四种类型数据的乘法。
实验内容:
1. 按下摇杆的UP键, 串口打印输出结果
实验现象:
        通过窗口上位机软件SecureCRT(V5光盘里面有此软件)查看打印信息现象如下:
8.4.png
程序设计:
  1. /*0 b6 m' d5 q! s: `2 x; Q( h
  2. *********************************************************************************************************
    3 K) Y9 N; ]$ d
  3. *        函 数 名: DSP_Multiplication. h  N; _' \7 j$ v( G; @# e
  4. *        功能说明: 乘法
    " `, G' `2 Q3 |  x" M, o3 `2 P
  5. *        形    参:无; c( d& W( R" {! P! K7 S6 ?
  6. *        返 回 值: 无
    7 h; y* t9 b1 K. v6 v' [
  7. *********************************************************************************************************9 [% b' u% f  X
  8. */
    ! l; H# M1 L6 T/ M/ w
  9. static void DSP_Multiplication(void)& R  |- \+ r0 L/ k: @) W
  10. {
    # B8 p7 H  e8 n0 f# v8 b
  11. static float32_t   pSrcA[5] = {1.0f,1.0f,1.0f,1.0f,1.0f};
    ; G. O* O: L& ^1 d0 h' R
  12. static float32_t   pSrcB[5] = {1.0f,1.0f,1.0f,1.0f,1.0f};    s# y2 x. E6 ^9 T% n
  13. static float32_t   pDst[5];  
    - d/ ?4 y" p1 y% _8 g* ]: k/ x* Z
  14. static q31_t  pSrcA1[5] = {1,1,1,1,1};  1 X/ T9 R+ i/ v3 U# ]
  15. static q31_t  pSrcB1[5] = {1,1,1,1,1};  : M% B, V; y) }1 O& A
  16. static q31_t  pDst1[5];   
    . P2 l' C- S& ]7 {

  17. 0 r* H% W2 T8 }1 f! n
  18. static q15_t  pSrcA2[5] = {1,1,1,1,1};  
    : l! @% _2 p4 g1 p
  19. static q15_t  pSrcB2[5] = {1,1,1,1,1};  
    6 k+ [6 A4 y. t0 \; d
  20. static q15_t  pDst2[5];   4 ~2 M% c7 g1 {3 ^9 E1 M
  21. - ~0 I* p; \, Y$ e; ^9 A
  22. static q7_t  pSrcA3[5] = {0x70,1,1,1,1}; , f9 Q$ J, d4 b" W" J9 b# {/ @3 N+ r
  23. static q7_t  pSrcB3[5] = {0x7f,1,1,1,1};  4 _. [( i0 K6 e$ s/ w- p
  24. static q7_t pDst3[5];  - Z$ ]# M5 x5 z* w1 c

  25. , b! ~9 |; Y5 |$ J: }
  26. pSrcA[0] += 1.1f;* H2 _# W* R4 t
  27. arm_mult_f32(pSrcA, pSrcB, pDst, 5);
    6 R5 K- L0 }: n8 }3 ~
  28. printf("arm_mult_f32 = %f\r\n", pDst[0]);
    1 F( q; p0 w7 x( w" R  g5 k
  29. pSrcA1[0] += 1;
    # N# T7 u6 n& v: N
  30. arm_mult_q31(pSrcA1, pSrcB1, pDst1, 5);
    , E" c& [2 ?: M3 _4 Z+ G+ ~6 ^7 G. `
  31. printf("arm_mult_q31 = %d\r\n", pDst1[0]);
    - B0 J- F5 i# `* O1 _; S- b9 r& ~
  32. 2 g9 k% t3 [# B% p. n
  33. pSrcA2[0] += 1;
    - m) \# k7 R' E% J7 e6 u) Z# Q
  34. arm_mult_q15(pSrcA2, pSrcB2, pDst2, 5);
    % X1 o& |# E& ^! k" A0 A1 \8 U
  35. printf("arm_mult_q15 = %d\r\n", pDst2[0]);
    ' p  e0 m) T2 }  p  A
  36. 0 a6 q3 @7 J' q8 ]* i4 b1 |# [
  37. pSrcA3[0] += 1;
    & `% c, u0 G5 V
  38. arm_mult_q7(pSrcA3, pSrcB3, pDst3, 5);
    6 x. K- ~0 P4 L8 g
  39. printf("arm_mult_q7 = %d\r\n", pDst3[0]);
    0 c& J4 x! E8 x& @
  40. printf("***********************************\r\n");$ v4 k- B0 A$ D) Z. C3 F5 u
  41. }
复制代码
$ z9 a* C- ~; `# P4 @
8.5 总结
    本期教程就跟大家讲这么多,还是那句话,可以自己写些代码调用本期教程中讲的这几个函数,如果可以的话,可以自己尝试直接调用这些DSP指令。
# j. V4 g& z, M2 F5 g% {
MouseCat 回答时间:2015-3-18 11:48:26
沙发,收藏
kqh1120 回答时间:2015-3-18 13:48:34
谢谢分享啊 3.gif
关于
我们是谁
投资者关系
意法半导体可持续发展举措
创新与技术
意法半导体官网
联系我们
联系ST分支机构
寻找销售人员和分销渠道
社区
媒体中心
活动与培训
隐私策略
隐私策略
Cookies管理
行使您的权利
官方最新发布
人形机器人运动控制、感知与智能配电
半导体创新技术与应用方向
EE架构与软件定义汽车
12V/48V 汽车智能配电(SPD)
区域控制单元(ZCU)与分区架构
关注我们
st-img 微信公众号
st-img 手机版