本帖最后由 咕噜 于 2015-4-19 18:25 编辑 4 y6 K; T( _4 D! r- T+ ^7 Q
" W# \- r* \8 @. w# X8 T7 N( q
原帖地址
/ p# r- {; C& ]( U( E& Hhttp://www.ichanging.org/uip-webserver.html+ J8 \ _6 f3 Z0 X! o- `
这篇帖子写的不错,分享一下。对于理解uIP很有帮助。8 o. s. T1 Z& l' R) X
Uip的Webserver比较复杂,用c语言实现一个简单服务器的所有功能,路由功能,GET传参,动态页面生成等。
8 R% c9 T- @ o" |, u7 l5 f8 k要运行Uip的WebServer 只需要:( P s( D$ i! Z7 s; d& `; P8 u4 F
1. 修改uip-con.h 里的#inlcude "webserver.h" 去除其注释* m) Z0 A- {7 v; W. r0 a3 z
2. 在User/main.c 里加入 httpd_init(); //初始化服务器
/ b' q( c( V2 R$ {* r4 [+ ~8 m1 t# VUip+ stm32移植参见 Uip + Stm32移植问题总结 % ~! O6 M- I* _9 \: E/ P4 K
浏览器访问 Uip WebServer 页面:
+ u! t3 l) H# A p1 n2 z. @; h
" p+ W* B; ]" y分析下 Uip Webserver 的运行过程,Uip WebServer使用到相关文件如下:( L6 {4 f1 X; b( k& M" D
1 ?# u3 \8 `! j+ P! S: u5 z0 g1 hhttpd.c ) G: K+ N6 T6 k# V: V4 f
httpd.c中定义了一些ASCII码,含义如下% P" Y( O- f* }6 L: i, e/ V
- #define ISO_nl 0x0a // 换行& @) ?: O& {/ t4 q L4 N" ?8 Y
- #define ISO_space 0x20 // 空格
/ q' e0 Z# C, m4 j; \* d - #define ISO_bang 0x21 // !3 Y: c) P7 X9 }3 C, {
- #define ISO_percent 0x25 // %$ l6 L! U( B. u3 K1 E
- #define ISO_period 0x2e // .4 s8 ?: l$ h* R3 M# V$ k' B
- #define ISO_slash 0x2f // /: n5 C$ h9 Z! C- T. R/ X) o4 M
- #define ISO_colon 0x3a // :
1 J) h6 |4 S. _; W7 Z/ H当Uip接收到Uip接收到底层传递的数据,将接收到的数据通过调用http_appcall(),传递给Webserver处理,再通过handle_connection()先后调用handle_input()函数和handle_output()函数
2 Q% E/ q2 o3 y0 rhandle_input()主要作用是分析http数据流:. D" o* D" E1 K9 S# t
0 ~# G! w3 A+ u) p, v, q
- static PT_THREAD(handle_input(struct httpd_state *s)) //分析http数据流, http数据流格式(eg. "GET /6?user=123 HTTP/ ...")
. w6 Q7 y% o+ g. a - {7 D0 p1 B( w; E( A7 m+ @. M( m" g
- char * ptr;- D; Z5 ` h9 ~ ?
-
, }' T: U6 H; A& t - PSOCK_BEGIN(&s->sin);+ o7 L, y* C: i9 H$ g; m
-
& O5 W$ z) N& @ - //取出到下一个空格号之前的数据5 U6 C* t- y4 h" {% S- i: _/ S
- PSOCK_READTO(&s->sin, ISO_space); //Uip使用这个函数从http数据流中剥离数据& X; V: z' S6 R" E3 D7 m
-
1 H' b; @7 j3 q# l$ I7 |7 ~ - 5 @. i2 U( [; y4 ^
- if(strncmp(s->inputbuf, http_get, 4) != 0) { //判断数据流前4位字符是否为"GET ",判断是否为GET传参
2 }! g0 P9 y! @ - PSOCK_CLOSE_EXIT(&s->sin);
+ L. |: E& Y' \+ _' e# b - }
* s+ H. O3 H* e* [ -
! w. w J0 h' u# B) z1 N1 D - PSOCK_READTO(&s->sin, ISO_space);8 P- Z4 A. K. d; R4 w
- 6 Y# W! y- O4 T0 U# z
- if(s->inputbuf[0] != ISO_slash) { 6 t1 I z: R5 u; A" ^# ]
- PSOCK_CLOSE_EXIT(&s->sin);+ w4 s: Z" V+ z4 Q' B
- }
& B- K9 D2 X5 u% Y8 M -
, X$ ?' ]* r" c/ f" a6 P* { - if(s->inputbuf[1] == ISO_space) { //请求路径为 "/ " (eg. 192.168.1.15/ ) 更新请求页面filename 为/index.html; y/ \) m$ G% f& P7 K$ t8 N8 A' L! P5 p- o
- strncpy(s->filename, http_index_html, sizeof(s->filename));6 M- ]+ O$ ]6 K* b
- } else { //根据请求路径,更新结构体中filename为相应页面名称1 m) [% d1 Z: j0 A' |$ E
- s->inputbuf[PSOCK_DATALEN(&s->sin) - 1] = 0;
q) l1 p5 \ R W - strncpy(s->filename, &s->inputbuf[0], sizeof(s->filename));
( d$ t* p* u( K/ @6 P5 y6 N/ _ - }
9 G# U* J# J% a9 h* C- P - 7 [) I3 Q' ]6 b% b
- /* httpd_log_file(uip_conn->ripaddr, s->filename);*/$ O) z" s h9 D$ N. O0 ?& o
-
" _$ _; {. d4 E - s->state = STATE_OUTPUT;
4 L- X0 Z$ d8 Q - ; n. f/ [/ G, b' ]/ w6 T! T
- while(1) {0 z' y# C. e. b0 j) |# j, S0 x
- PSOCK_READTO(&s->sin, ISO_nl);
9 q0 O0 |' O7 c3 w) n" u -
# u, o' n6 h& Q! y' N& v0 \$ K - if(strncmp(s->inputbuf, http_referer, 8) == 0) {
# Z6 Q9 x# d+ a" v& h - s->inputbuf[PSOCK_DATALEN(&s->sin) - 2] = 0;
+ M7 }" O( F! ^* g& }# ~" c - /* httpd_log(&s->inputbuf[9]);*/
1 j* O @/ `6 a3 _8 }, h - }
9 V0 R0 Z! {; O - }) P" k+ x% o: q0 X$ |5 \$ i
- 0 w/ y5 b, z r8 f; a
- PSOCK_END(&s->sin);
/ T$ q2 f7 c, @0 y) d, B - }
- m" y( g G# X" i! T- static PT_THREAD(handle_output(struct httpd_state *s))3 `4 M9 `' }$ ^( j9 M
- {; c+ k+ F$ e( ?- E7 A
- char *ptr;
, X$ Z/ a9 B9 ]& t, X -
, U6 b5 m g1 e; m- Q - PT_BEGIN(&s->outputpt);- k& Z G( r, _8 b) i
- ! n; T i2 q& `$ I6 u0 ]( f \
- if(!httpd_fs_open(s->filename, &s->file)) { //没有此页面,打开404页面
2 `' `/ k- j& l4 l - httpd_fs_open(http_404_html, &s->file);
* }+ C* P9 A! q - strcpy(s->filename, http_404_html);) I/ L; {2 U; v8 U: Y
- PT_WAIT_THREAD(&s->outputpt,- x( J* l E& U
- send_headers(s,/ T8 q1 m- r5 [% z, e
- http_header_404));
8 a) b' c6 C1 ^# t- o% M8 i' V - PT_WAIT_THREAD(&s->outputpt,
* F5 T$ x/ ^# A2 m - send_file(s));- z% t( {3 r; u. U5 Y" S
- } else { //正常打印相应页面
" n6 {5 X) ]) a3 c# z! O& c" } - PT_WAIT_THREAD(&s->outputpt,
2 g; O% ]/ p( f6 [, \9 |$ H - send_headers(s,
$ @& _& o) {& [' a* ]: P - http_header_200));
7 \; I" G5 S0 R1 K( V - ptr = strchr(s->filename, ISO_period); //查找字符串s->filename中首次出现字符ISO_period的位置,返回首次出现c的位置的指针
% i2 _- b2 v* f L' B - if(ptr != NULL && strncmp(ptr, http_shtml, 6) == 0) { //判断是否为 .shtml网页文件 . ]# x* Z# v4 l% A- u) `
- PT_INIT(&s->scriptpt);6 ~3 _5 }2 f8 ?8 U8 }% Y' B1 T
- PT_WAIT_THREAD(&s->outputpt, handle_script(s)); //若为 .shtml页面,则调用handle_script()生成动态网页- @- w+ V; k. J* z* H
- } else { //不是 .shtml(eg. /index.html),输出该页面数据
8 s/ L( g5 e! d; z - PT_WAIT_THREAD(&s->outputpt,
/ q6 P6 [2 ^ @# U8 \" o! f% b2 o0 a - send_file(s));8 j, R4 j9 G: J: U+ Z4 [5 N
- }$ K6 c) ~- M- z* v) T4 N
- }! y! L; e: I, B% p' e
- PSOCK_CLOSE(&s->sout);/ H+ m# H# ^# R
- PT_END(&s->outputpt);- n: [) Z! u0 @; v' ?. k
- }
httpd_fs_open()定义于httpd-fs.c,用于读取相应页面的数据,将页面数据存入全局结构体中,是实现路由遍历的关键函数:- g; @) w S) O" V
- int httpd_fs_open(const char *name, struct httpd_fs_file *file)+ Y( C5 t% \6 p$ |/ a2 o y
- {
3 _3 E: O. `) G - #if HTTPD_FS_STATISTICS" ?# ?* r! I/ l+ A5 q5 v
- u16_t i = 0;
5 l: U% ~& t% n6 A$ J" D# a1 D$ _9 B - #endif /* HTTPD_FS_STATISTICS */8 v$ G7 @. _" s: Y B$ R/ l
- struct httpd_fsdata_file_noconst *f;
# i, R" h8 t9 K6 x4 Z$ m9 m
http-fsdata.c 中包含了所有页面的数据。这里的页面数据都转换为ACAll存在数组中,还包括了层叠样式表 (.css文件) 和图片。其数组结构如下:- D c& F( |2 K
! ~) P, n2 y. m: B- static const unsigned char data_404_html[] = {
. z' O7 x! c& B: u - /* /404.html */6 Z& {- @6 O5 P! o( x/ S+ I% ^
- 0x2f, 0x34, 0x30, 0x34, 0x2e, 0x68, 0x74, 0x6d, 0x6c, 0, //文件名 /404.html
0 `2 Y3 l: ^4 D9 v -
6 \& p1 S4 c: r! Q# v- p - 0x3c, 0x68, 0x74, 0x6d, 0x6c, 0x3e, 0xa, 0x20, 0x20, 0x3c, //html文件转码为16进制数据(ASCLL)1 V% s8 u" k1 H! D+ I
- 0x62, 0x6f, 0x64, 0x79, 0x20, 0x62, 0x67, 0x63, 0x6f, 0x6c,
; J# _1 P% g# x2 A) N - 0x6f, 0x72, 0x3d, 0x22, 0x77, 0x68, 0x69, 0x74, 0x65, 0x22,
l: ?) g0 v( k0 _5 U, T1 Y - 0x3e, 0xa, 0x20, 0x20, 0x20, 0x20, 0x3c, 0x63, 0x65, 0x6e,
" N! p }4 j' ^0 L: a - 0x74, 0x65, 0x72, 0x3e, 0xa, 0x20, 0x20, 0x20, 0x20, 0x20,
) g# O$ S/ [: u- g# W - 0x20, 0x3c, 0x68, 0x31, 0x3e, 0x34, 0x30, 0x34, 0x20, 0x2d,
4 D3 S( D Y* p, _6 G. F - 0x20, 0x66, 0x69, 0x6c, 0x65, 0x20, 0x6e, 0x6f, 0x74, 0x20,
% `3 l) I; E# I, Z6 d5 ~ - 0x66, 0x6f, 0x75, 0x6e, 0x64, 0x3c, 0x2f, 0x68, 0x31, 0x3e, b7 d0 X9 U4 m. s: S
- 0xa, 0x20, 0x20, 0x20, 0x20, 0x20, 0x20, 0x3c, 0x68, 0x33,
8 m9 U5 w% W1 c" z - 0x3e, 0x47, 0x6f, 0x20, 0x3c, 0x61, 0x20, 0x68, 0x72, 0x65,
. Z; w! e9 {6 \% n( k) ]0 u9 K' Q - 0x66, 0x3d, 0x22, 0x2f, 0x22, 0x3e, 0x68, 0x65, 0x72, 0x65, 0 p6 Q, W4 X- q- t1 k
- 0x3c, 0x2f, 0x61, 0x3e, 0x20, 0x69, 0x6e, 0x73, 0x74, 0x65, , f7 [+ s1 d8 ^$ }, f! f. K0 j
- 0x61, 0x64, 0x2e, 0x3c, 0x2f, 0x68, 0x33, 0x3e, 0xa, 0x20,
% T" b, i% O) i - 0x20, 0x20, 0x20, 0x3c, 0x2f, 0x63, 0x65, 0x6e, 0x74, 0x65,
6 d! N1 j- [% h `) f% w - 0x72, 0x3e, 0xa, 0x20, 0x20, 0x3c, 0x2f, 0x62, 0x6f, 0x64,
3 \: L8 C* z, |0 L - 0x79, 0x3e, 0xa, 0x3c, 0x2f, 0x68, 0x74, 0x6d, 0x6c, 0x3e, " {+ Q: S. _2 y# H4 @1 P8 C: S
- 0};
需要注意的是以下的一段程序:- //结构体格式说明: 下一个页面地址(用于遍历网页) ,网页name地址 ,html数据起始地址 ,html数据长度
2 u4 M& n2 h5 p2 s o. u - //其中的加减操作是为了去除文件名的长度9 X% Q5 M5 [; b$ `
- const struct httpd_fsdata_file file_processes_shtml[] = {{NULL, data_processes_shtml, data_processes_shtml + 17, sizeof(data_processes_shtml) - 17}};
, d. R8 o4 K* \% e5 |5 r -
7 {( Z+ ?. x% _# d - const struct httpd_fsdata_file file_404_html[] = {{file_processes_shtml, data_404_html, data_404_html + 10, sizeof(data_404_html) - 10}};) i6 @( h' ]5 S% \
- $ r( e: e3 \ g" i8 I8 r- g1 A
- const struct httpd_fsdata_file file_files_shtml[] = {{file_404_html, data_files_shtml, data_files_shtml + 13, sizeof(data_files_shtml) - 13}};8 f; R4 ?& U9 }, e3 A6 B: b+ ]
- " w" t8 `3 V4 j) r ?. t
- const struct httpd_fsdata_file file_footer_html[] = {{file_files_shtml, data_footer_html, data_footer_html + 13, sizeof(data_footer_html) - 13}};- ^( q* k: K1 B' C! g u0 @5 O# I. p5 u+ v
- Z9 v1 p+ Y5 v* m$ B: j
- const struct httpd_fsdata_file file_header_html[] = {{file_footer_html, data_header_html, data_header_html + 13, sizeof(data_header_html) - 13}};
' Q: A( X- [; p* G2 u3 U/ K% a/ d* N - 0 w5 U/ i' Q! U0 Z) j
- const struct httpd_fsdata_file file_index_html[] = {{file_header_html, data_index_html, data_index_html + 12, sizeof(data_index_html) - 12}};
+ i, |1 _/ `4 P% P9 Y6 } - & f3 J& z/ f: |; d0 y
- const struct httpd_fsdata_file file_style_css[] = {{file_index_html, data_style_css, data_style_css + 11, sizeof(data_style_css) - 11}};
; m. Y7 W' W# H9 H7 O4 M/ t -
8 [! X+ U" k! W$ w9 [( @ - const struct httpd_fsdata_file file_tcp_shtml[] = {{file_style_css, data_tcp_shtml, data_tcp_shtml + 11, sizeof(data_tcp_shtml) - 11}};- \, S6 j) X: L4 E9 m: W z
- * u7 o# P/ @. Y
- const struct httpd_fsdata_file file_fade_png[] = {{file_tcp_shtml, data_fade_png, data_fade_png + 10, sizeof(data_fade_png) - 10}};" s! p( A! N& @
-
5 Q- A; k4 E4 Q+ F* u& U8 C - const struct httpd_fsdata_file file_stats_shtml[] = {{file_fade_png, data_stats_shtml, data_stats_shtml + 13, sizeof(data_stats_shtml) - 13}};
/ J* Q! n6 q5 z2 m -
- S8 k1 z: U3 q. v# k' n" \5 w - #define HTTPD_FS_ROOT file_stats_shtml //设定路由遍历入口页面,一定要保证所有页面都遍历过一次6 I- T9 f3 c, v2 m
- / x7 \3 D$ D: w9 P, q
- #define HTTPD_FS_NUMFILES 10 //设定页面数量
在 httpd_fs_open() 首先加载 file_stats_shtml页面数据 再加载file_stats_shtml结构体中下一个网页的数据 也就是file_fade_png的数据,同理 file_fade_png加载后一个页面数据 即 file_tcp_shtml数据 。。。 这样循环一次 就会加载所有的页面,实现里有遍历
: O; X, _0 h3 A1 E7 q+ Y3 @Uip WebServer的动态网页生成
+ e2 a6 ~& n4 }: f8 I! l在uip/apps/Webserver/http-fs/下有Webserver 页面未转码的html文件,其中有很多 %! 和 %!: 字符 :; J6 x; T' K r. u5 G
- %!: /header.html
: K/ i+ P5 L3 J- ~ - <h1>Network statistics</h1>2 @4 Z6 P; |5 [( K, b
- <center>" i. P: f% L+ B
- <table width="300" border="0">, O" K3 z5 a2 u. U
- <tr><td><pre>
2 Z2 A7 I' S5 p4 e( j/ f( d* L - IP Packets received; W2 e; e( K& v9 \8 G
- Packets sent. d; i+ h: @, m k8 l" X9 F
- Packets dropped
2 g4 K! ^% _1 D4 A4 u/ S0 q - IP errors IP version/header length
1 Q8 z3 N$ `" K, f4 @ - IP length, high byte6 y* }) G: G2 x; y' j& I8 i; v
- IP length, low byte- D+ _" X' V' `7 m0 q; [
- IP fragments$ p! e8 t) L5 h+ s) j v2 T$ _8 c
- Header checksum
6 }: f8 f' {7 O* L4 `! r - Wrong protocol/ E9 f) c9 r* c* _
- ICMP Packets received
* ]7 I" Z( H; p* `; i7 U - Packets sent
( c7 g# V2 _- y/ f) ]! f - Packets dropped! Q6 e6 W& a' x
- Type errors
5 n" V; b0 b+ ~ - TCP Packets received
! ?' W+ w- {, y# r - Packets sent
6 C3 ?! m, m+ y& ]4 \0 C - Packets dropped
. a. g4 |7 p2 ?0 S - Checksum errors R" f8 Y. s) }: C6 j; k
- Data packets without ACKs
8 R, f0 X( A! M3 V! F" G- Z. o - Resets
! Q2 @3 M9 o# n. H" _ - Retransmissions
: z" J. e. ]2 }! |( w. t, J( g' L' d, D! Z - No connection avaliable
* ?9 ~8 h' X9 g8 F$ k+ Y - Connection attempts to closed ports
0 ^1 R. I" i; {: l" {- T8 g8 w: h - </pre></td><td><pre>%! net-stats1 f* j, R* ~ I4 N( `
- </pre></table>. J9 I) f8 }% o5 b
- </center>
; s) A( ?# H: ^6 z5 V5 K) q7 Y - %!: /footer.html
" s# o; M. @! S/ \/ rhandle_output()函数中,找到相应页面数据后,若页面为.shtml,则会调用handle_script()函数:- static PT_THREAD(handle_script(struct httpd_state *s))
$ z: r+ s# K+ P0 B0 V6 C - {1 W" C5 _& }, O, q4 r1 p4 E+ d; o
- char *ptr;
7 d7 h; b. r( a- K( A4 b1 y4 k2 j0 t -
" @1 m) i' o+ b7 G# L* W - PT_BEGIN(&s->scriptpt);0 e8 ~/ D; Z _
-
6 a' m6 i# i8 r6 s) {. X -
9 I/ I6 y. U3 _" } - while(s->file.len > 0) {
5 v w. q+ H: V9 X, |( D -
) [7 Q: N0 @$ j2 r9 w, r0 y - /* Check if we should start executing a script. */ //检测当前html数据(定义于httpd-fsdata.c)中是否存在字符 %! 和 %!:
4 P/ t' y8 w0 Q' c+ A: C - if(*s->file.data == ISO_percent &&
9 d3 [# e7 k% X, t3 G0 k - *(s->file.data + 1) == ISO_bang) {
* ]% ] Z' S$ [/ I - s->scriptptr = s->file.data + 3;
a5 V: P$ I2 ?6 k0 U - s->scriptlen = s->file.len - 3;/ Q( ?% O, m; y- H
- if(*(s->scriptptr - 1) == ISO_colon) { //若为 %!: 根据其后变量名,打开并输出相应文件 1 ^+ `8 m9 a2 s8 ?
- httpd_fs_open(s->scriptptr + 1, &s->file); //eg. %!: /header.html 打印/header.html. }' b" p$ [& C3 b$ b7 \ z
- PT_WAIT_THREAD(&s->scriptpt, send_file(s));* y) X& X( Y! `. R% I y8 \
- } else { //若为 %! 根据其后变量名,调用相应处理程序(定义于httpd-cgi.c)
" w: h( K- L6 X! g8 T8 f - PT_WAIT_THREAD(&s->scriptpt, //eg. %! file-stats 调用file-stats 绑定的file_stats()函数,打印出相关数据,实现动态网页
& \+ l1 r" _/ v4 X - httpd_cgi(s->scriptptr)(s, s->scriptptr));
* I' Z7 [, V8 _+ j Y1 p - } f6 c, Q/ F% ^' M& ]$ O0 D; t
- next_scriptstate(s);
2 m" `$ V$ O" C) t - - k& U. b, V T5 c
- /* The script is over, so we reset the pointers and continue
- F; D4 `4 u# p, M6 G0 W* R) V - sending the rest of the file. */. Q4 D- ^$ c/ @: p/ v8 f: Q& [
- s->file.data = s->scriptptr;) V' S+ p4 f \* P& o
- s->file.len = s->scriptlen;
8 f) B/ |; k8 W2 f# B - } else { //当前html数据不存在 %! 和 %!
* W# o4 C0 O0 c* Q6 M$ S - /* See if we find the start of script marker in the block of HTML/ d# T; d8 Z, e( \3 n( {" Z% x9 m# m
- to be sent. */5 @3 \9 @6 H0 x. r, _# u" r% U
- # h& S" p" z. q* r" {4 e
- ...略去
$ L3 [8 p6 E! [uip 载入html数据的方法类似网页里的模板引擎的实现方法。当页面输出时,检测到有字符串 %! 和 %!: 时,则调用相应的cgi程序(httpd-cgi.c)处理,在httpd-cgi.c中做相应的数据处理,实现动态网页。 {% R' f3 _2 H$ u: x$ a
( m6 m, c' z; A
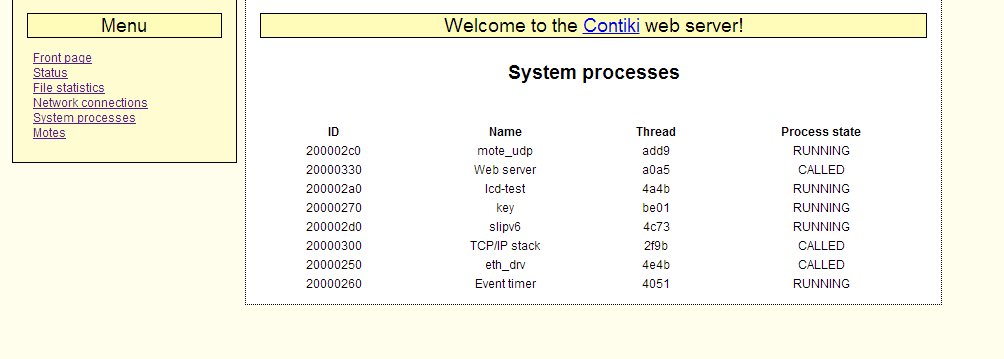
# \' P7 z' @5 G- P9 Q看一下效果吧
3 M9 Z& z5 z$ g
$ F% g& S" I r6 R( `( X
! t0 Q, z" O1 i% ~7 W |





 微信公众号
 手机版


